12 Decode and KV-cache layout
Decode optimization focuses on the repeated one-token step. A small inefficiency in one step becomes large when repeated for thousands of generated tokens across many active requests. Decode is therefore a scheduling, memory-layout, and cache-management problem as much as a model-forward problem.
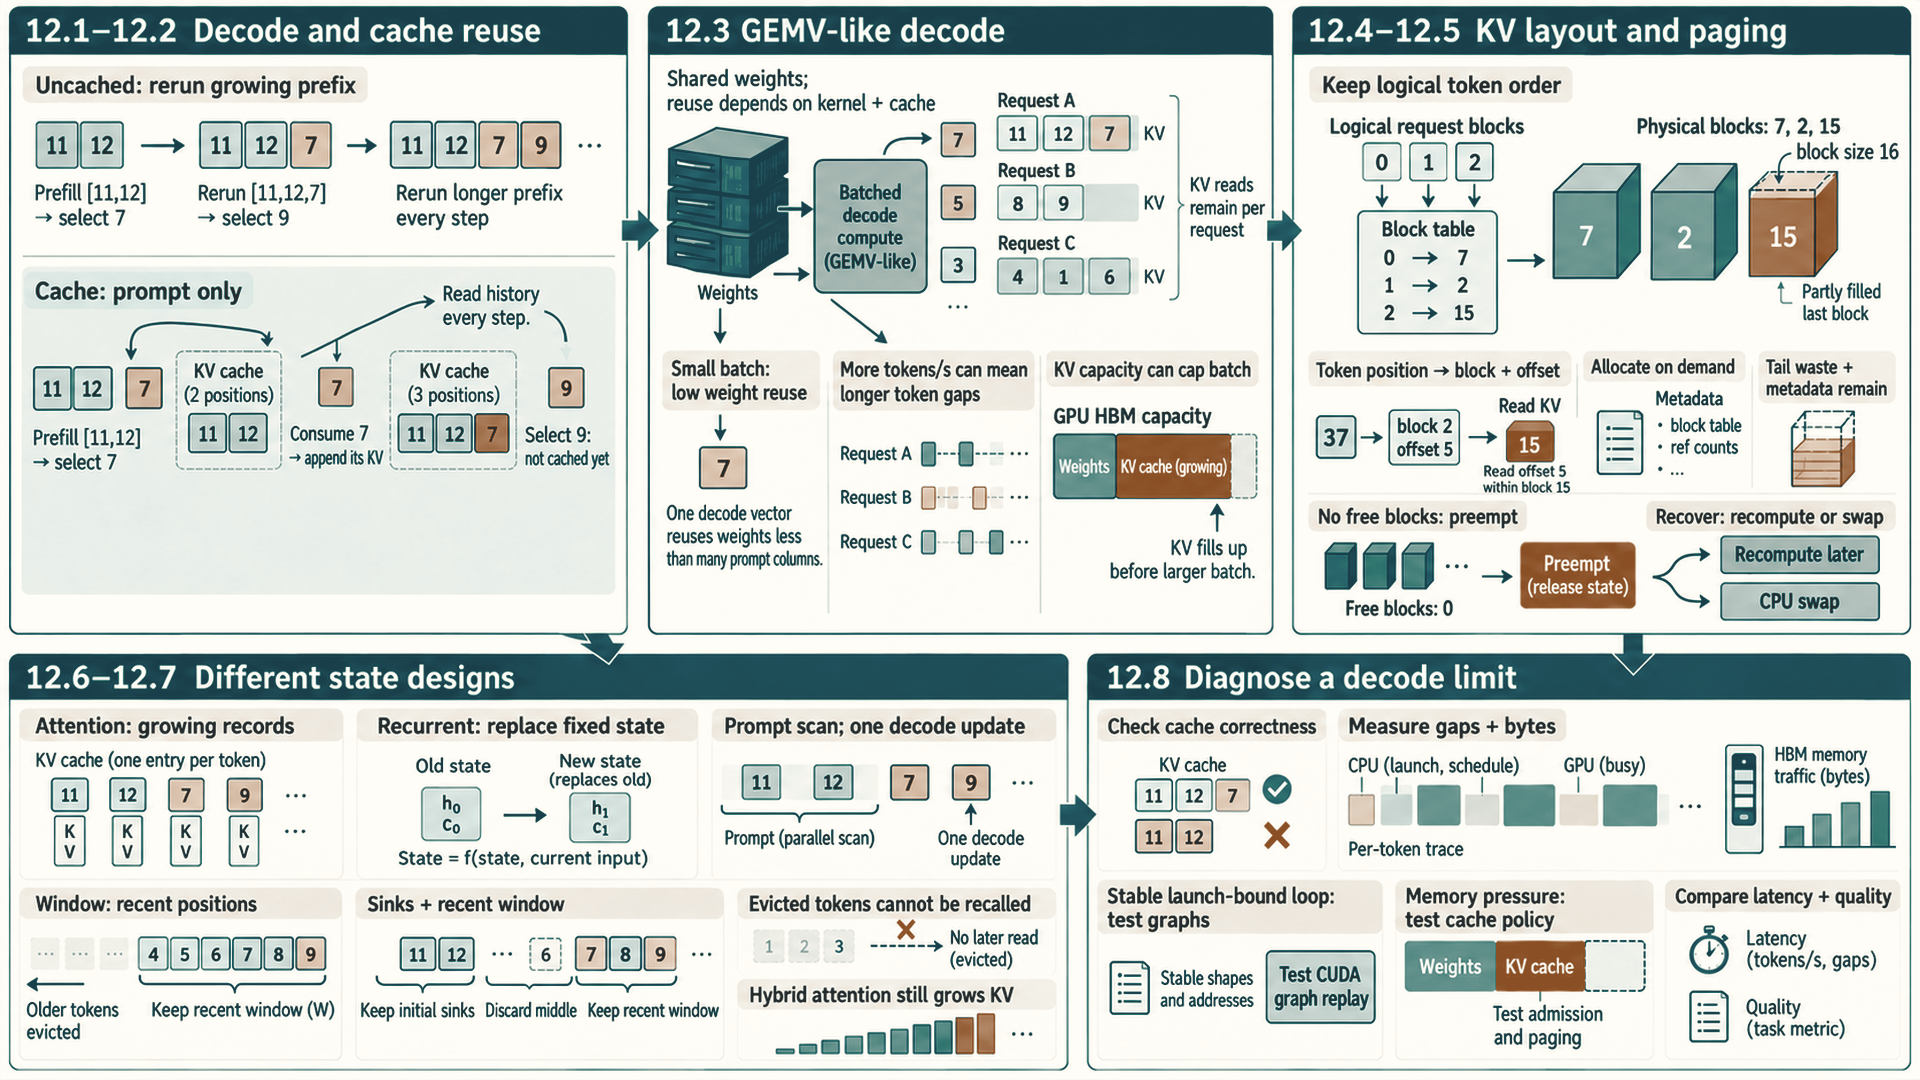
The key-value cache avoids recomputing the full prefix, but it also becomes the largest dynamic memory object in long-context serving. Cache layout determines whether decode kernels read memory efficiently. Allocation policy determines how many requests can be admitted without waste.
12.1 Decode loop anatomy
Autoregressive generation uses prefill to predict the first output token, then decode steps to predict later tokens. A naive loop may rerun the model over the growing prefix. Let the prompt contain \(P\) tokens and let the model generate \(G\) new tokens without a cache. The first generation pass processes \(P\) tokens. Later passes process every prefix length from \(P+1\) through \(P+G-1\). Across all \(G\) outputs, projection and other per-token layer work therefore processes
\[ \sum_{j=0}^{G-1}(P+j)=GP+\frac{G(G-1)}{2} \]
token positions. Dense full-prefix attention accumulates work proportional to
\[ \sum_{j=0}^{G-1}(P+j)^2=GP^2+PG(G-1)+\frac{G(G-1)(2G-1)}{6}. \]
This becomes cubic in \(G\) only when generated length grows large relative to the fixed prompt. Caching avoids repeating the old key and value projections, but each new query still attends to a growing history. After prefill, the \(j\)th single-token decode call attends to \(P+j\) positions, including its current input token.
For a concrete state trace, suppose the prompt has token IDs [11, 12]. Prefill processes both positions, returns their keys and values, and produces scores that select token 7. Selection has not sent 7 through the model, so the returned cache still covers only the two prompt positions. The next decode call sends [7] with that cache. The model computes 7’s new keys and values, reads the earlier two positions, and returns a cache for three positions. Its scores may select token 9; 9 is not in the cache until a later call consumes it. Thus two calls can select two output tokens while the returned cache covers the prompt and only the first selected output token.
Example: Cached decode loop
This is a parameterized callable fragment, not a complete run from a fresh Python session. It needs a compatible causal model already loaded in evaluation mode on the same device as nonempty torch.long prompt IDs shaped [batch, prompt_length]; prompts in a batch have equal length and no padding. The model must return .logits and .past_key_values, accept past_key_values and use_cache=True on later calls, and infer the next input’s position from the cache. Models requiring an attention mask, position IDs, or cache_position need an adapted call. With those inputs and a positive requested count, the fragment returns only the newly selected greedy token IDs, shaped [batch, count]. A nonpositive count returns an empty [batch, 0] tensor without a model call. It has no EOS stopping and is not a serving scheduler or universal generation wrapper.
Code example: Cached decode loop
import torch

@torch.inference_mode()
def cached_decode(model, input_ids, max_new_tokens):
    if max_new_tokens <= 0:
        return torch.empty((input_ids.size(0), 0), dtype=input_ids.dtype, device=input_ids.device)

    out = model(input_ids, use_cache=True)
    past = out.past_key_values
    token = out.logits[:, -1].argmax(dim=-1, keepdim=True)
    generated = [token]

    for _ in range(max_new_tokens - 1):
        out = model(token, past_key_values=past, use_cache=True)
        past = out.past_key_values
        token = out.logits[:, -1].argmax(dim=-1, keepdim=True)
        generated.append(token)

    return torch.cat(generated, dim=1)
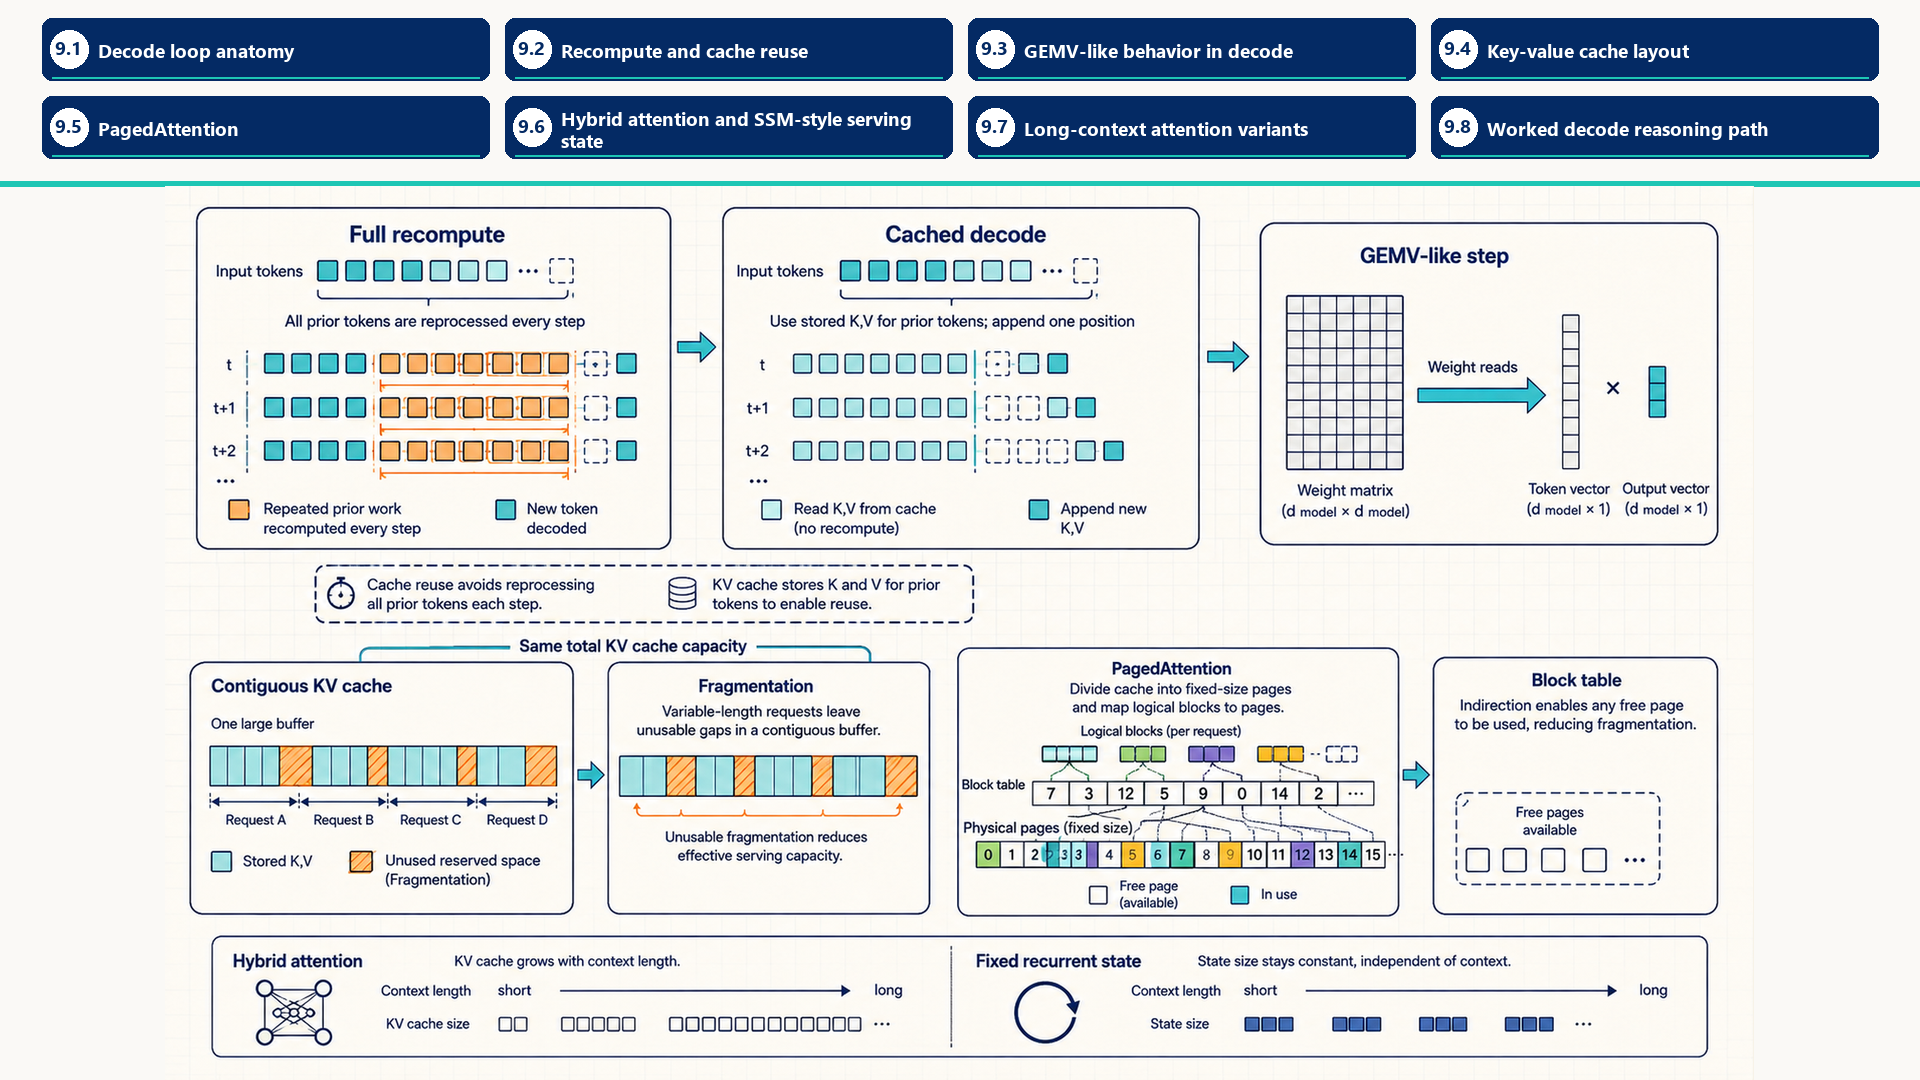
The first call processes the prompt and retains its returned cache. Each later call consumes the previous selected token with that cache, replaces the cache with the returned state, and selects the next token. Selection alone does not add the newly chosen token to KV state, as the trace above shows. Attention still reads a cache that grows with context length, so removing prefix recomputation does not make each step constant-cost. The remaining work is often sensitive to memory bandwidth and per-step launch overhead.
12.2 Recompute and cache reuse
Decode implementations trade one cost for another. The three variants below move from recomputation to persistent state and then to runtime-managed execution, but their ranking depends on request size, batch, cache pressure, and implementation overhead.
- Naive decode: Every new token recomputes attention over the whole prefix from scratch. It is simple but quickly becomes wasteful because history is processed repeatedly.
- Cached decode: The model stores key and value tensors from previous tokens. Each new step processes only the newest token and attends to cached history, trading recomputation for persistent memory reads.
- Optimized decode: The serving stack reduces launch overhead, improves batching, lays out cache reads efficiently, pages KV memory, and avoids allocator churn.
This progression explains why a cached loop can be much faster than naive recomputation while still performing poorly in production. Once recomputation is gone, decode is often limited by reading weights and KV cache, maintaining enough active sequences, and launching repeated small steps without CPU gaps.
12.3 GEMV-like behavior in decode
A model can have high theoretical FLOP/s during prefill and still produce slow tokens during decode because workload shape and model size determine whether decode maps to a compute-rich matrix-matrix multiply (GEMM) or to a bandwidth-sensitive path that behaves like a matrix-vector multiply (GEMV).
Section 4.7 defined GEMM and GEMV, and Section 6.2 showed why their arithmetic intensity differs. The distinction matters because matrix-matrix work reuses loaded weights across many output columns, while matrix-vector work often reads many weights for only one or a few token vectors.
- GEMV-like decode: A small-batch decode step multiplies large projection matrices by one or a few token vectors. Weight reuse is low, so arithmetic intensity is low.
- GEMM-like prefill: Prompt processing uses many token positions at once, so the same weights can be reused across a larger matrix of activations. This is usually better for tensor-core utilization.
- Bandwidth implication: Small-batch decode may be dominated by reading model weights and KV cache rather than by raw arithmetic throughput.
- Batching implication: With continuous batching, the scheduler removes finished requests and admits waiting ones at token-step boundaries. Grouping active requests can make the decode step less vector-like by increasing useful work per launch, but latency and KV-cache capacity still constrain it. Chapter 13 compares the scheduling policies.
The whole decode step follows the reasoning of Section 6.2. For a dense model whose weights must be fetched from HBM each step, an ideal batch-size-one pass reads each required weight once to produce one token, so the time per token cannot be shorter than the weight bytes divided by the HBM bandwidth. The KV cache adds its own bytes, and those bytes are normally separate for each sequence unless the engine reuses shared-prefix blocks.
Example: A coarse decode traffic estimate for an 8B model
Inputs: Use a coarse Llama 3 8B-class estimate with an assumed 16 GB of weight traffic per decode step and 131,072 KV bytes read per retained token (Section 2.1). The 16 GB comes from \(8\times10^9\) BF16 parameters, but stored size does not establish mandatory traffic: the input embedding selects one row, and cache reuse can reduce HBM reads (Section 1.1). Use 3.35 TB/s for H100 SXM HBM bandwidth. The model reads the assumed weight and KV bytes once at that bandwidth and ignores activations. Its times are ideal estimates for those assumptions. A strict lower bound for an actual execution requires the bytes its executed operations must fetch from HBM.
| Sequences \(B\) | Tokens each \(T\) | Assumed weight traffic | Assumed KV traffic | Ideal time for assumed traffic | Ideal tokens/s, all sequences |
|---|---|---|---|---|---|
| 1 | 8,192 | 16.0 GB | 1.07 GB | 5.1 ms | 196 |
| 32 | 2,048 | 16.0 GB | 8.6 GB | 7.3 ms | 4,360 |
| 32 | 8,192 | 16.0 GB | 34.4 GB | 15.0 ms | 2,129 |
| 345 | 2,048 | 16.0 GB | 92.6 GB | Not admitted on 80 GB | Not admitted on 80 GB |
Arithmetic check: At \(B=32\) the weight multiplications need \(2\times8\times10^9\times32\approx5.1\times10^{11}\) FLOPs, about 0.52 ms at the 989 TFLOP/s peak. The traffic-only estimate is 7.3 to 15.0 ms, larger than the arithmetic estimate in this model. A measured run can still be limited by launch overhead, inefficient kernels, or scheduling.
Conclusion: In this ideal model, batching shares one read of the weights among all sequences. The tabulated ideal times give throughput estimates for the assumed traffic: their ratios are about 11 to 22, while each request’s modeled token interval rises from 5.1 ms to 7.3 or 15.0 ms. Actual batching gains require measurements. With activation traffic omitted, the weight multiplications have arithmetic intensity \(B\) FLOPs per byte: \(2 \times 8\) billion parameters times \(B\) sequences, divided by 16 billion weight bytes. Their ridge point is therefore near \(989/3.35 \approx 295\) sequences. At 295 sequences of 2,048 tokens, raw KV storage is 79.2 GB; adding 16 GB of weights exceeds one 80 GB GPU before other state. The approximately 345-sequence result in Section 6.2 instead includes activation traffic for one 4,096-square projection. For the shapes and retained lengths here, KV-cache capacity can limit the decode batch before the arithmetic units become the limit.
Attention does not improve with batching the way the weight multiplications do. For each cached token, the 32 query heads of a Llama 3 8B layer perform \(4\times32\times128\) FLOPs (a score and a weighted sum per query head) on \(2\times8\times128\times2\) bytes of keys and values. Under this full-KV-read model, with key/value reuse across the query heads sharing each KV head, the intensity is 4 FLOP per byte independent of batch size. The HBM roofline ceiling is lower than the BF16 arithmetic ceiling for this attention calculation. Measurements still distinguish a bandwidth limit from launch, occupancy, latency, or access-pattern limits. The levers are fewer or smaller cache entries: grouped-query attention (Section 10.6), KV-cache quantization (Section 11.1), and the long-context variants of Section 12.7.
12.4 Key-value cache layout
Long-context decode streams a growing key-value cache, so layout decides both whether attention kernels read efficiently and how many requests fit in memory.
Key-value cache layout is the physical organization of cached key and value tensors in GPU High Bandwidth Memory (HBM). It specifies how layers, sequences, token positions, heads, and head dimensions are ordered, and how the serving engine finds the cache blocks for each active request during attention.
Each layer keeps ordered key and value records for active sequences. Decode appends state when a model call processes a token, then later attention reads prior records. Merely selecting the next token does not append it. Layout must make both operations and block lookup efficient.
- Layer dimension: Each transformer layer stores its own key and value tensors because attention state is layer-specific.
- Sequence and token dimensions: The cache must preserve token order for each request, even when physical blocks are not contiguous.
- Head and head-dimension layout: The arrangement of KV heads and per-head vector elements affects whether attention kernels can read contiguous addresses.
- Append path: Each token processed by a cached model call adds new keys and values. Selecting the next token alone does not append it. The layout must make this write path cheap enough for repeated decode steps.
- Read path: Every decode step rereads prior keys and values for attention. This read path is often more important than append cost for long contexts.
- Block table: Paged layouts add metadata mapping logical token blocks to physical cache blocks, trading lookup indirection for lower memory waste.
A cache layout should support coalesced reads by attention kernels, efficient append of new keys and values, and fast lookup for each active sequence. Grouped-query attention reduces the number of key-value heads and therefore cache size. Quantizing the cache can reduce bandwidth, but only if the attention path supports the format efficiently.
Hardware L1/L2 cache is managed by the GPU. A serving engine manages the KV cache for active decoding, retained prefix blocks for later requests, and any KV blocks moved to CPU, disk, or remote storage. These policies have different owners and lifetimes.
One word, four meanings: cache
Hardware cache: the L1 and L2 storage between the SMs and HBM (Section 3.2). Software influences it through access patterns and supported cache hints or persistence controls, while hardware still manages cache-line placement and eviction1.
KV cache: the keys and values kept in HBM so that a decode step does not recompute the whole prefix (Section 12.1). The serving engine decides what stays there, which is why layout, block size, and paging policy are optimization objects at all.
Prefix cache: KV blocks kept after a request finishes so that a later request with the same opening tokens can reuse them (Section 13.5).
External KV cache layer: KV blocks moved out of GPU memory into host memory or storage, to be fetched back when needed (Section 13.5.3).
Only the first is hardware-managed. The other three are engine policies. This chapter develops KV layout and paging. The request-scheduling chapter develops prefix reuse and external KV-cache policies.
KV blocks usually live in HBM and are reread by attention kernels at every decode step. The L2 cache may help when accesses are nearby or repeated, but long-context decode can stream through more KV data than the hardware cache holds, so the reliable objects to change are KV layout, block size, paging policy, attention-kernel tiling, and request locality.
12.5 PagedAttention
PagedAttention is a KV-cache management technique that maps logical token blocks in a sequence to reusable physical KV-cache blocks in GPU memory2. The idea is similar to virtual memory: a request has an ordered logical sequence, while the engine is free to place the underlying physical blocks wherever capacity is available.
The problem is variable sequence length. If an engine reserves one large contiguous KV region for the maximum possible output length of every request, short completions leave unused space and long-running service can fragment memory. Other contiguous allocators may reserve less and have different waste patterns. Paging reduces this waste by allocating fixed-size blocks on demand.
It does not remove all waste: partially filled final blocks, block tables, metadata work, and indirect kernel addressing remain.
The block table is the central mechanism. Each request has a logical sequence of KV blocks: block 0, block 1, block 2, and so on. The engine maps those logical blocks to physical blocks in GPU memory. For example, request A may map logical blocks [0, 1, 2] to physical blocks [7, 2, 15]. Attention kernels use this mapping to gather the right keys and values even though the physical allocation is non-contiguous.
In the ideal case, all full blocks are packed and only the final block of an active sequence is partially empty. The trade-off is indirection: every request needs block-table metadata, and kernels or scheduler code must resolve logical positions to physical blocks.
| Dimension | Contiguous allocation | PagedAttention-style allocation |
|---|---|---|
| Memory reservation | Often reserves for maximum or estimated length | Allocates fixed-size blocks as needed |
| Fragmentation | Can waste space for short outputs | Reduces waste through block reuse |
| Lookup | Simple pointer arithmetic | Block-table indirection |
| Scheduler complexity | Lower | Higher, because block assignment must be tracked |
Paged allocation is most useful when variable request lengths make contiguous reservation waste enough HBM to limit admission. It changes cache allocation and lookup, not the attention formula, so kernel efficiency, scheduler fairness, and prefix-cache correctness remain separate measurements.
Paging also allows the engine to run out of free blocks while requests are still generating, because each running request keeps requesting new blocks. The engine must then stop some running requests and release their blocks, a step called preemption. vLLM 0.6.4 (an open-source serving engine, Section 13.1) defaults to recomputing a preempted single-sequence group’s KV cache once space becomes available. Groups with multiple sequences default to swapping: the engine copies evicted KV blocks to CPU memory and later restores them. An explicit preemption-mode setting can also select swap. Thus recovery can cost either recomputation or PCIe transfers, depending on the group and mode.3 The PagedAttention design describes both approaches. Recomputation can take less time than the original generation, because the prompt and the tokens generated so far are processed together as one prefill.4
Preemption can cause latency spikes for affected requests, so its rate belongs on the serving dashboard (Section 15.1). The vLLM documentation suggests more cache memory (gpu_memory_utilization), fewer concurrent sequences or batched tokens (max_num_seqs, max_num_batched_tokens), or more tensor parallelism.5 The useful choice depends on whether the run lacks cache capacity, spends too long recovering state, or exposes another limit.
Example: PagedAttention block lookup
This pseudocode maps a logical token position to a physical block and an offset within it. It illustrates the mapping rather than a particular engine implementation.
Code example: PagedAttention block lookup
block_size = 16
# request A: logical block -> physical KV block
block_table = {0: 7, 1: 2, 2: 15}

def physical_location(token_index):
    logical_block = token_index // block_size
    offset = token_index % block_size
    physical_block = block_table[logical_block]
    return physical_block, offset
The pseudocode implements only metadata translation from a logical token position to a physical block and offset. A complete implementation also accounts for layer, KV head, vector dimension, append writes, vectorized reads, and the attention kernel that consumes the resolved addresses. Conclusion: Block lookup trades indirection for less reserved capacity. Admission and latency measurements show whether that trade-off helps the workload.
The figure below compares how a cache can be allocated as requests grow.
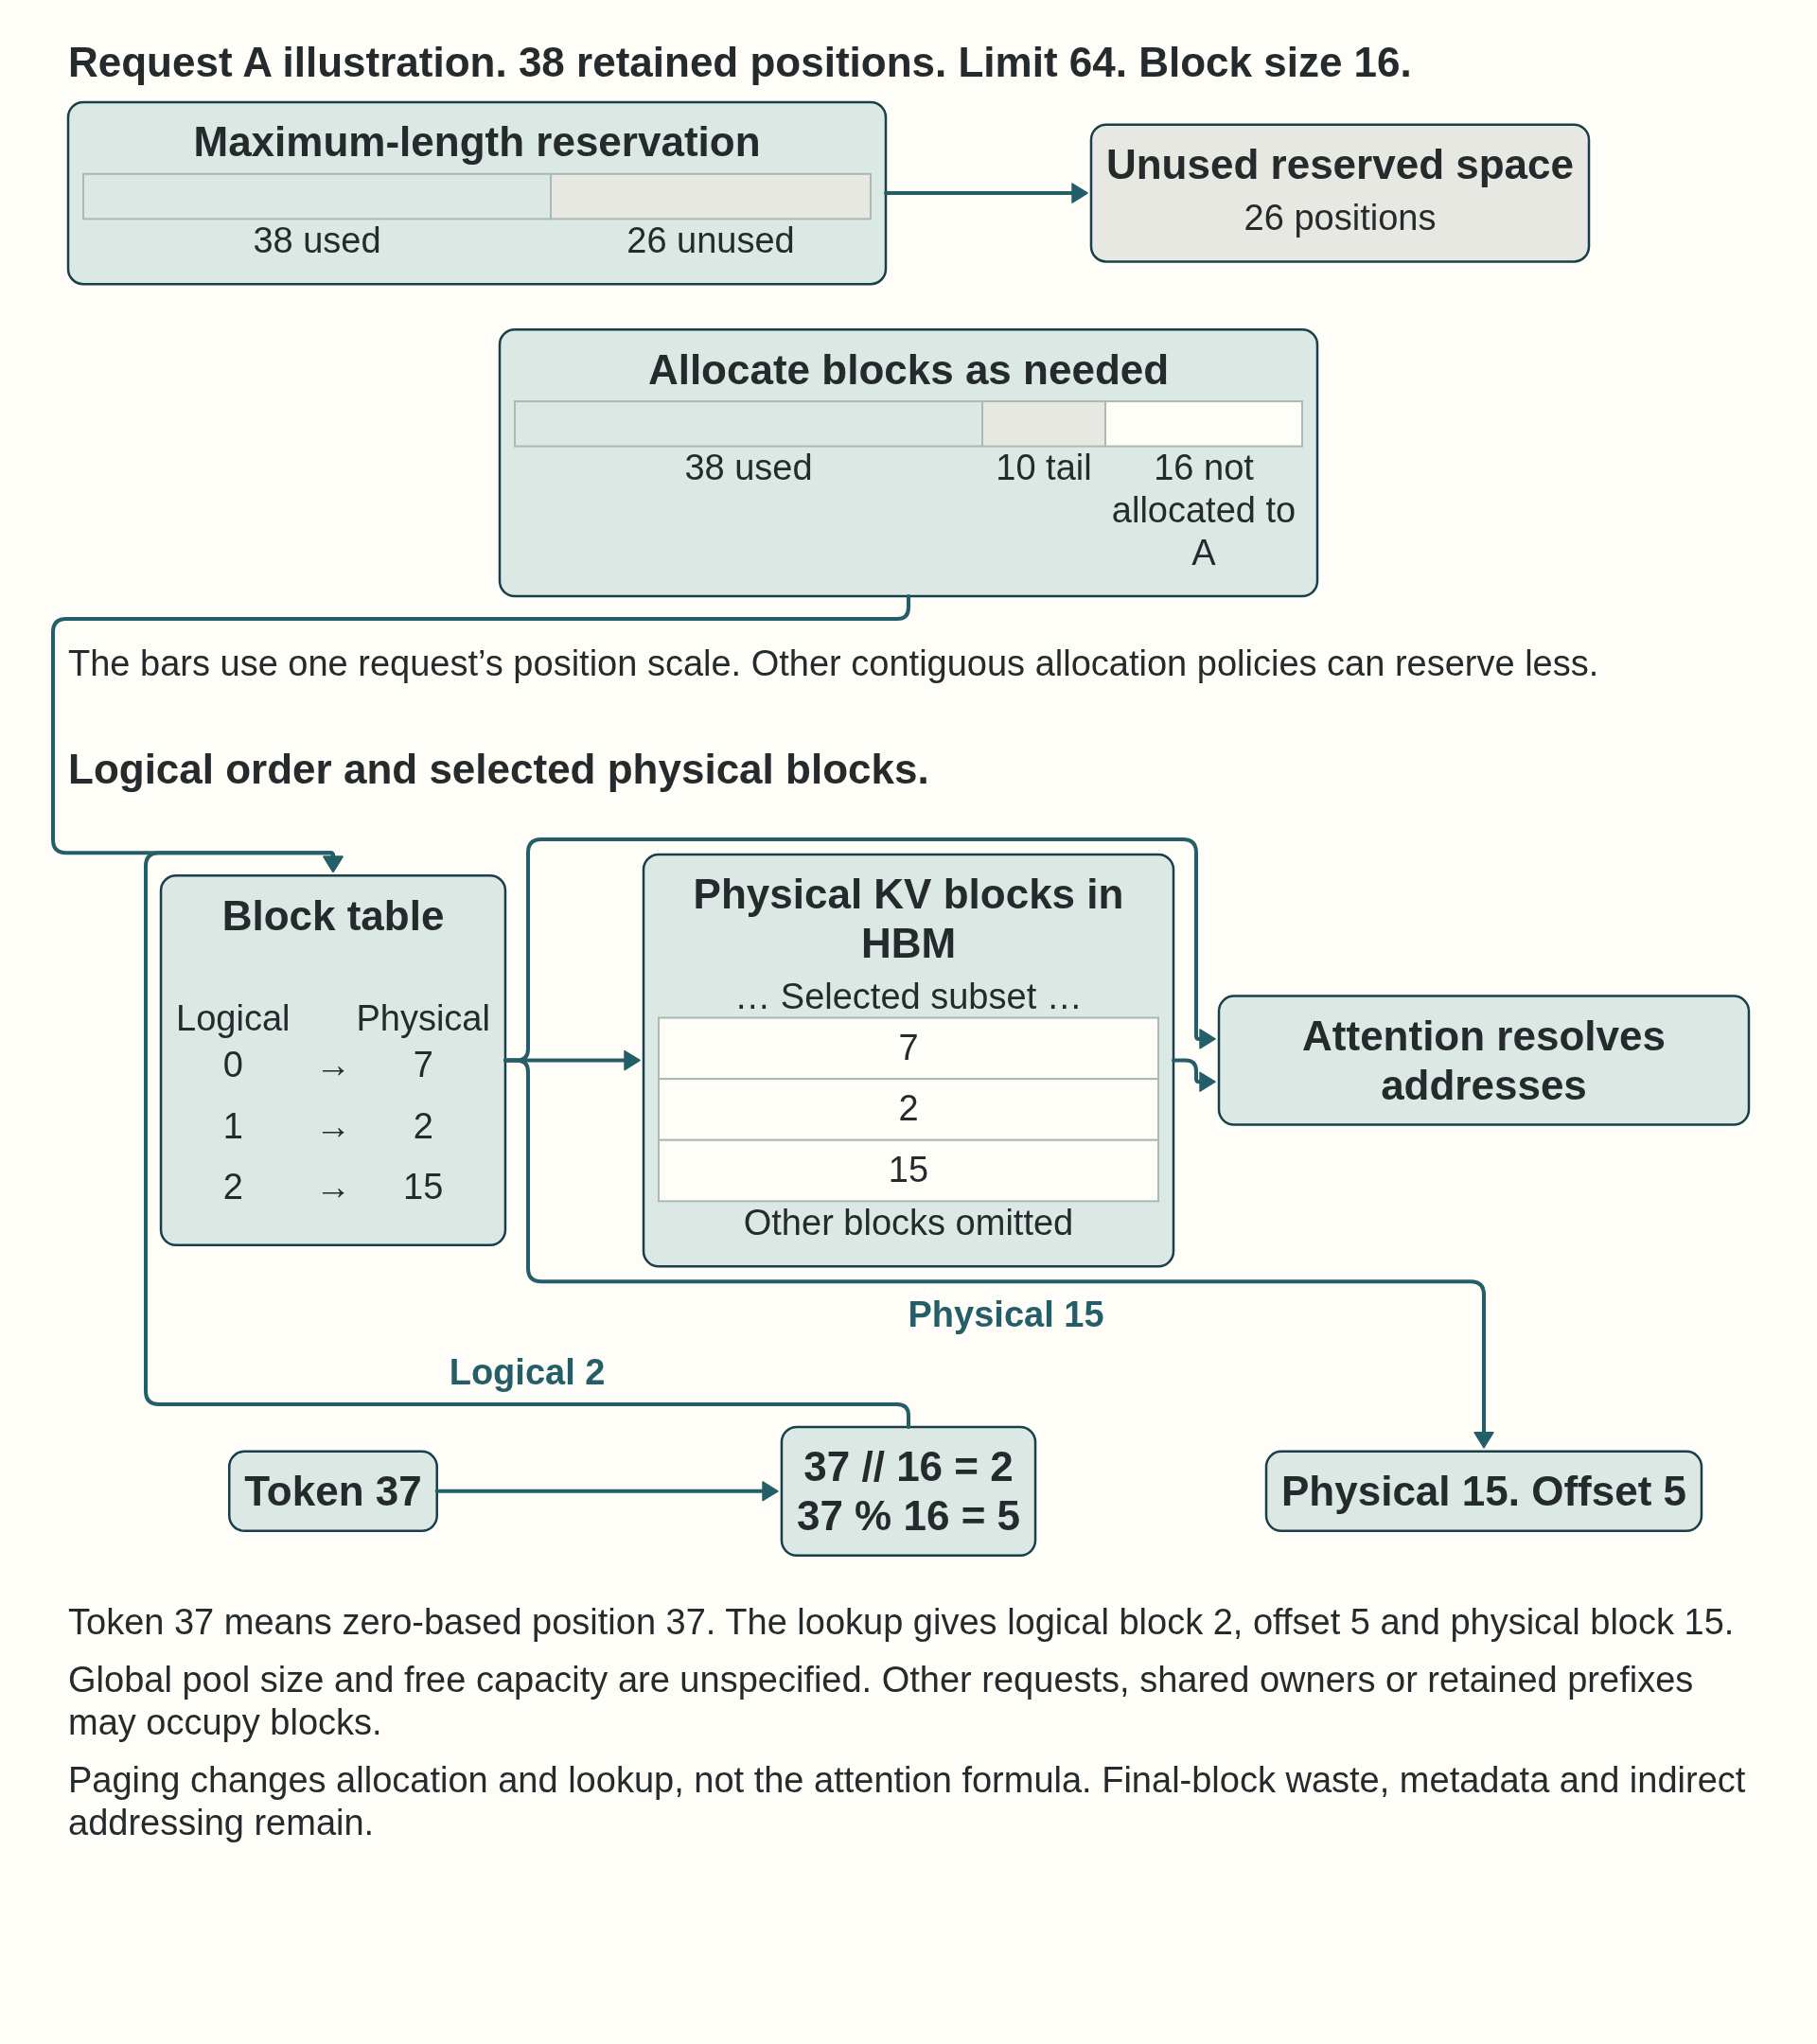
The allocation bars compare one request’s reservation with blocks allocated as its cache grows. Maximum-length reservation can leave unused positions inside that request’s reserved space. A block table maps logical blocks to non-contiguous physical blocks, with metadata, indirect addressing and final-block waste. Capacity not allocated to this request may still be held by other requests or retained prefixes. Fixed recurrent state is a different model design, not another KV layout.
12.6 Hybrid attention and SSM-style serving state
In a hybrid model that mixes attention layers with state-space or recurrent layers, attention layers still store one key and value record per retained token, so their state and read traffic grow with context length. The state-space or recurrent layers instead update a fixed-size hidden state for each sequence. In this architecture family, replacing some attention layers with recurrent layers can therefore reduce long-context KV capacity and bandwidth, but it changes the work rather than removing it. These objects are architecture-specific: the model and runtime documentation defines their scan or recurrent-update kernels, state layout, chunking, invalidation, and prefix rules. The recurrent state is a compressed summary, not an addressable record of every past token.
For a recurrent layer, the current token’s input features and the previous hidden state determine a new state and an output for the next layer. The worker reads the old state, computes the update, and retains the new state in its place. A state-space model (SSM) uses a structured state update and an output mapping. Selective SSMs such as Mamba allow parts of those mappings to depend on the current input6. The following fixed-coefficient recurrence isolates the storage behavior. It is not a complete Mamba block, a token predictor, or a model-quality comparison.
Example: Two tokens and a fixed state
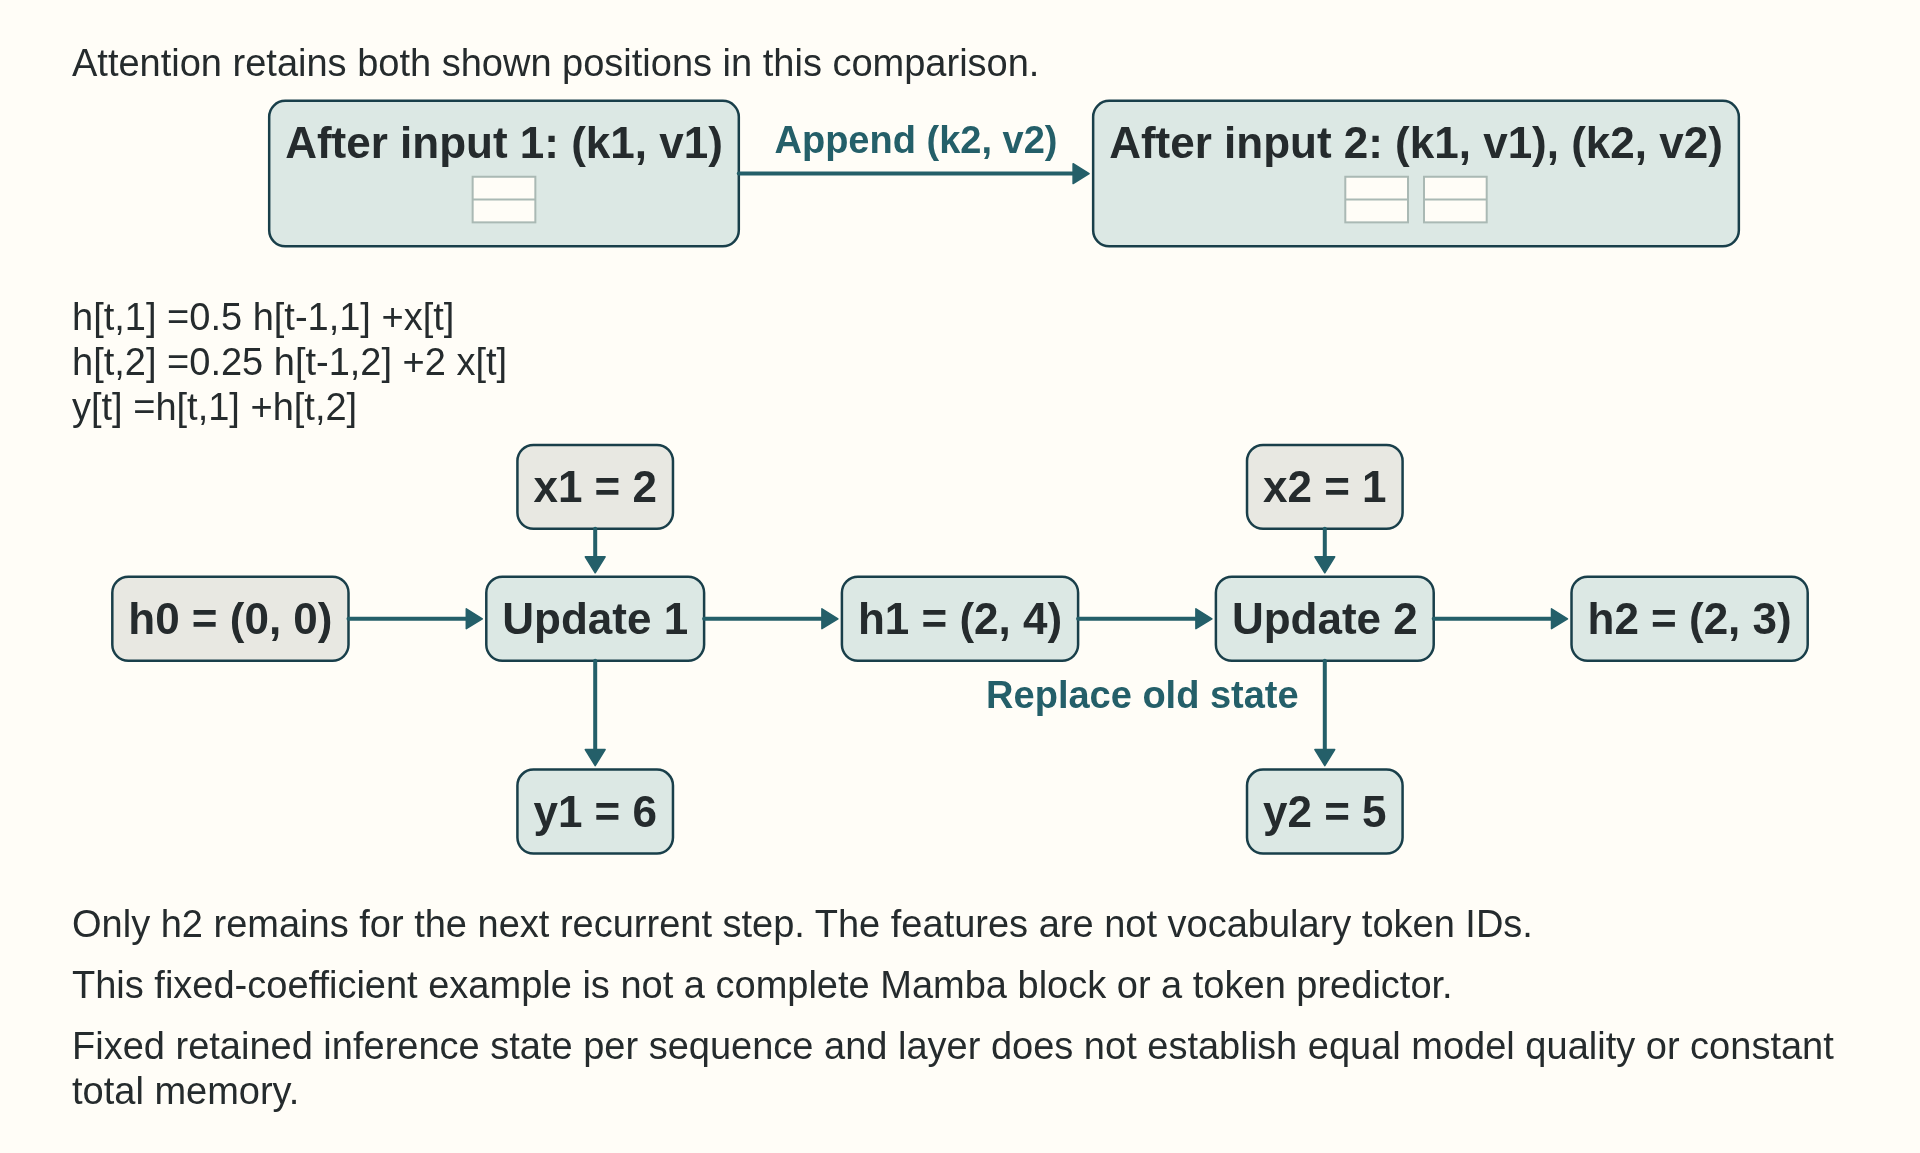
Inputs and task: In inference mode, let \(x_t\) be one scalar feature of token \(t\), rather than its vocabulary ID. The old state is a two-element vector \(h_{t-1}\), initially \(h_0=(0,0)\). Use fixed update rules \(h_{t,1}=0.5h_{t-1,1}+x_t\) and \(h_{t,2}=0.25h_{t-1,2}+2x_t\). The layer output is the scalar \(y_t=h_{t,1}+h_{t,2}\). The question is what must remain stored after processing features \(x_1=2\) and \(x_2=1\).
- At token 1, the retained contribution from \(h_0\) is \((0,0)\) and the input contributes \((2,4)\). The new state is \(h_1=(2,4)\) and the output is \(y_1=6\).
- At token 2, the old state contributes \((0.5(2),0.25(4))=(1,1)\) and the new input contributes \((1,2)\). The new state is \(h_2=(2,3)\) and the output is \(y_2=5\). It replaces \(h_1\) for subsequent recurrent execution.
Conclusion: The state still has two elements, but both contain contributions from earlier input. The worker retains \(h_2\), not a list of \(h_0,h_1,h_2\). An attention layer retaining these two token positions instead adds two KV records, \((k_1,v_1)\) and \((k_2,v_2)\), to its history. Fixed state shape limits recurrent storage growth but does not preserve separately addressable token records or establish equivalent model quality.
Prompt processing has all prompt inputs available. A scan computes the sequence of states obtained by applying the update through each input prefix. Suitable affine updates can be composed and evaluated with a parallel scan while preserving those dependencies. Single-token decode has only the newest input and carried state, so it performs one recurrent update. Chunked prompt execution passes the final state of one chunk into the next7.
Mamba-style serving therefore shifts attention toward scan kernels, recurrent updates, chunking, and state layout. Fixed recurrent state describes retained inference state per sequence and layer. It does not mean prompt outputs, temporary workspaces, or training activations take constant total memory. Hybrid models still retain growing KV history in their attention layers, and actual runtimes may also keep other architecture-specific state.
12.7 Long-context attention variants
The worked example in Section 12.3 showed that, at long contexts, the KV cache can outweigh the weights in both capacity and bytes read per step. Standard attention stores and rereads a key and a value for every retained token in every layer. Several design families reduce that state. They differ in whether they change the model, which must then be trained or adapted for them, and in what the model can no longer recall.
- Sliding-window attention: each layer attends only to the most recent \(W\) positions. Information from further back can still propagate through stacked layers. Mistral 7B uses \(W=4{,}096\), giving a theoretical attention span of about 131,000 tokens at the last layer, and its fixed-size rolling cache reduces cache memory by 8 times at 32,000 tokens without reported quality loss.8 The window is part of the model and is set during training.
- Attention sinks are tokens that receive unusually large attention weights even when their content is not important to the current prediction. StreamingLLM observed this behavior at the initial tokens and retains their KV entries plus a recent window, discarding the rest. In the tested Llama-2, MPT, Falcon, and Pythia models, keeping initial entries recovered the performance lost when plain window attention evicted them. These models, trained with a finite attention window, processed streams of up to 4 million tokens without fine-tuning; StreamingLLM achieved up to 22.2 times the speed of sliding-window recomputation.9 This does not expand the attention window. Evicted tokens cannot be recalled, so details from the middle of a long input may be lost.
- Latent KV compression: the model stores a compressed low-rank vector per token instead of full keys and values, and reconstructs what attention needs. DeepSeek-V2 uses Multi-head Latent Attention (MLA) for this compression. The complete DeepSeek-V2 model reduced KV cache by 93.3 percent and reached 5.76 times the maximum generation throughput of DeepSeek 67B. That comparison also includes other architectural changes.10 This also requires a model trained or adapted for the architecture.
- Fewer or narrower entries within standard attention: grouped-query attention (Section 10.6) and KV-cache quantization (Section 11.1).
- Spreading the context across GPUs: Context parallelism divides one long sequence among several devices at the cost of communication (Section 19.4).
Example: One 128k-token sequence
Inputs: Llama 3 8B-like shapes: 32 layers and head dimension 128. The sequence retains 131,072 tokens, and the cache is BF16 (2 bytes) unless stated otherwise. The KV bytes per sequence are \(2\times T\times L\times H_{\mathrm{kv}}\times d_h\times b\) (Section 10.6). These are raw payload sizes before scale metadata, block rounding, and other runtime overhead.
| Attention design | Tokens stored | KV heads | Bytes per element | KV cache for the sequence |
|---|---|---|---|---|
| Full multi-head attention | 131,072 | 32 | 2 | 64 GiB |
| Grouped-query attention | 131,072 | 8 | 2 | 16 GiB |
| Grouped-query attention, FP8 cache | 131,072 | 8 | 1 | 8 GiB |
| Grouped-query, 4,096-token window | 4,096 | 8 | 2 | 0.5 GiB |
Conclusion: At this length the attention design sets the memory budget: the same model shape needs between 0.5 and 64 GiB for one sequence. The smaller designs are not free. Grouped-query attention and windows require a model trained or adapted for those designs, quantization adds rounding error, and eviction forgets tokens, so each needs a quality check on long-context tasks (Section 11.4).
12.8 Diagnosing a decode limit
A decode bottleneck is assessed through the one-token path in a fixed order. The comparison begins with cached and uncached decode, then uses timeline and memory counters to determine whether repeated computation, GPU idle gaps, HBM traffic, or KV capacity currently limits the service metric.
Decision path: Diagnosing a decode bottleneck
- Step 1: naive and cached decode: A small caching benefit can reflect short prefixes, an already optimized baseline, cache-management overhead, incorrect cache use, or a limit outside prefix recomputation.
- Step 2: per-token trace: GPU gaps suggest launch overhead, Python scheduling, or delays while the engine schedules and submits work. A large HBM byte count with busy kernels makes bandwidth limitation a hypothesis. For the same kernel region, compare bytes divided by elapsed time with the applicable sustained HBM bandwidth, and compare achieved FLOP/s with the compute and arithmetic-intensity-based bandwidth ceilings from Section 6.3. Near-ceiling memory throughput with low math utilization supports the hypothesis. The counters and follow-up measurements in Section 7.2.2 distinguish it from launch, occupancy, or access-pattern limits. A controlled reduction in transferred bytes that lowers decode time at fixed workload and acceptable quality provides further evidence. Paging alone may improve admission without reducing the bytes read for an already-admitted request.
- Step 3: stable single-worker loop: Compilation or CUDA Graph replay applies when shapes and memory addresses are stable and profiler traces show launch-bound behavior.
- Step 4: useful batch size: Continuous batching can recover utilization while time to first token (TTFT), time per output token (TPOT), and cache capacity remain within the service target.
- Step 5: cache-memory pressure: PagedAttention, prefix reuse, grouped-query attention, or KV-cache quantization become relevant when cache allocation or HBM bandwidth limits admission or latency.
The resulting optimization sequence is workload-specific. Separate prefill from repeated decode, validate KV-cache updates, measure per-token latency, then test whether memory bandwidth, launch overhead, or scheduler gaps limit the fixed workload. A short-output chatbot, a long-context retrieval system, and a high-throughput batch generator can expose different bottlenecks even with the same model.
These changes operate inside one worker’s decode and cache path. The request-scheduling chapter next decides which requests advance together and which prefixes can be reused. The following decoding chapter then examines speculative proposals and output constraints, including the result each method must preserve.
References
NVIDIA. (n.d.). CUDA Programming Guide, L2 Cache Control. Retrieved September 28, 2026, from L2 Cache Control. Describes streaming and persisting access preferences and the L2 set-aside controls. These controls influence retention where supported; they do not guarantee that every requested cache line remains resident.↩︎
Kwon, W., et al. (2023). Efficient Memory Management for Large Language Model Serving with PagedAttention. In SOSP 2023. arXiv:2309.06180. PagedAttention paper. Supports partitioning KV cache into fixed size blocks mapped non-contiguously through a block table, cutting fragmentation and bounding waste to the final partial block plus metadata. Limit: block tables, metadata and indirection remain, and prefix sharing correctness still needs separate checks.↩︎
vLLM contributors. (n.d.). Performance and Tuning, Preemption (v0.6.4.post1 guide), Engine Arguments (v0.6.4.post1 mode setting), and v0.6.4 scheduler source. The scheduler’s
_preemptchooses recomputation by default for one running sequence and swap for a multi-sequence group; explicit swap overrides that default. The guide describes cache pressure and suggested mitigations. Later releases can change these policies and settings.↩︎Kwon, W., et al. (2023). Efficient Memory Management for Large Language Model Serving with PagedAttention. In SOSP 2023. arXiv:2309.06180. PagedAttention paper. Supports partitioning KV cache into fixed size blocks mapped non-contiguously through a block table, cutting fragmentation and bounding waste to the final partial block plus metadata. Limit: block tables, metadata and indirection remain, and prefix sharing correctness still needs separate checks.↩︎
vLLM contributors. (n.d.). Performance and Tuning, Preemption (v0.6.4.post1 guide), Engine Arguments (v0.6.4.post1 mode setting), and v0.6.4 scheduler source. The scheduler’s
_preemptchooses recomputation by default for one running sequence and swap for a multi-sequence group; explicit swap overrides that default. The guide describes cache pressure and suggested mitigations. Later releases can change these policies and settings.↩︎Gu, A., & Dao, T. (2023). Mamba: Linear-Time Sequence Modeling with Selective State Spaces. arXiv:2312.00752. Mamba paper. Supports input dependent selective SSMs with a hardware aware recurrent scan that keeps state fixed size, scales linearly in length, and avoids per-step KV growth. Limit: the recurrent state is a compressed summary rather than addressable history, and scan kernels, chunking and layout are architecture and runtime specific.↩︎
Gu, A., & Dao, T. (2023). Mamba: Linear-Time Sequence Modeling with Selective State Spaces. arXiv:2312.00752. Mamba paper. Supports input dependent selective SSMs with a hardware aware recurrent scan that keeps state fixed size, scales linearly in length, and avoids per-step KV growth. Limit: the recurrent state is a compressed summary rather than addressable history, and scan kernels, chunking and layout are architecture and runtime specific.↩︎
Jiang, A. Q., et al. (2023). Mistral 7B. arXiv:2310.06825. Supports sliding-window attention with W = 4,096, a theoretical attention span of about 131K tokens at the last layer, and a rolling buffer cache that reduces cache memory by 8x on 32k-token sequences without impacting model quality in the paper’s tests. Limit: the quality statement applies to the paper’s evaluations.↩︎
Xiao, G., Tian, Y., Chen, B., Han, S., & Lewis, M. (2024). Efficient Streaming Language Models with Attention Sinks. ICLR 2024. arXiv:2309.17453. Supports the attention-sink observation, that keeping the KV of initial tokens recovers window-attention performance, streaming to 4 million tokens without fine-tuning, and up to 22.2x speedup over sliding-window recomputation. Limit: evicted tokens are not available to later attention.↩︎
DeepSeek-AI. (2024). DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model. arXiv:2405.04434. Supports Multi-head Latent Attention with low-rank key-value joint compression, a 93.3 percent KV-cache reduction and 5.76x maximum generation throughput relative to DeepSeek 67B. Limit: the comparison is between two specific models and also reflects other architectural changes.↩︎