11 Model compression for inference
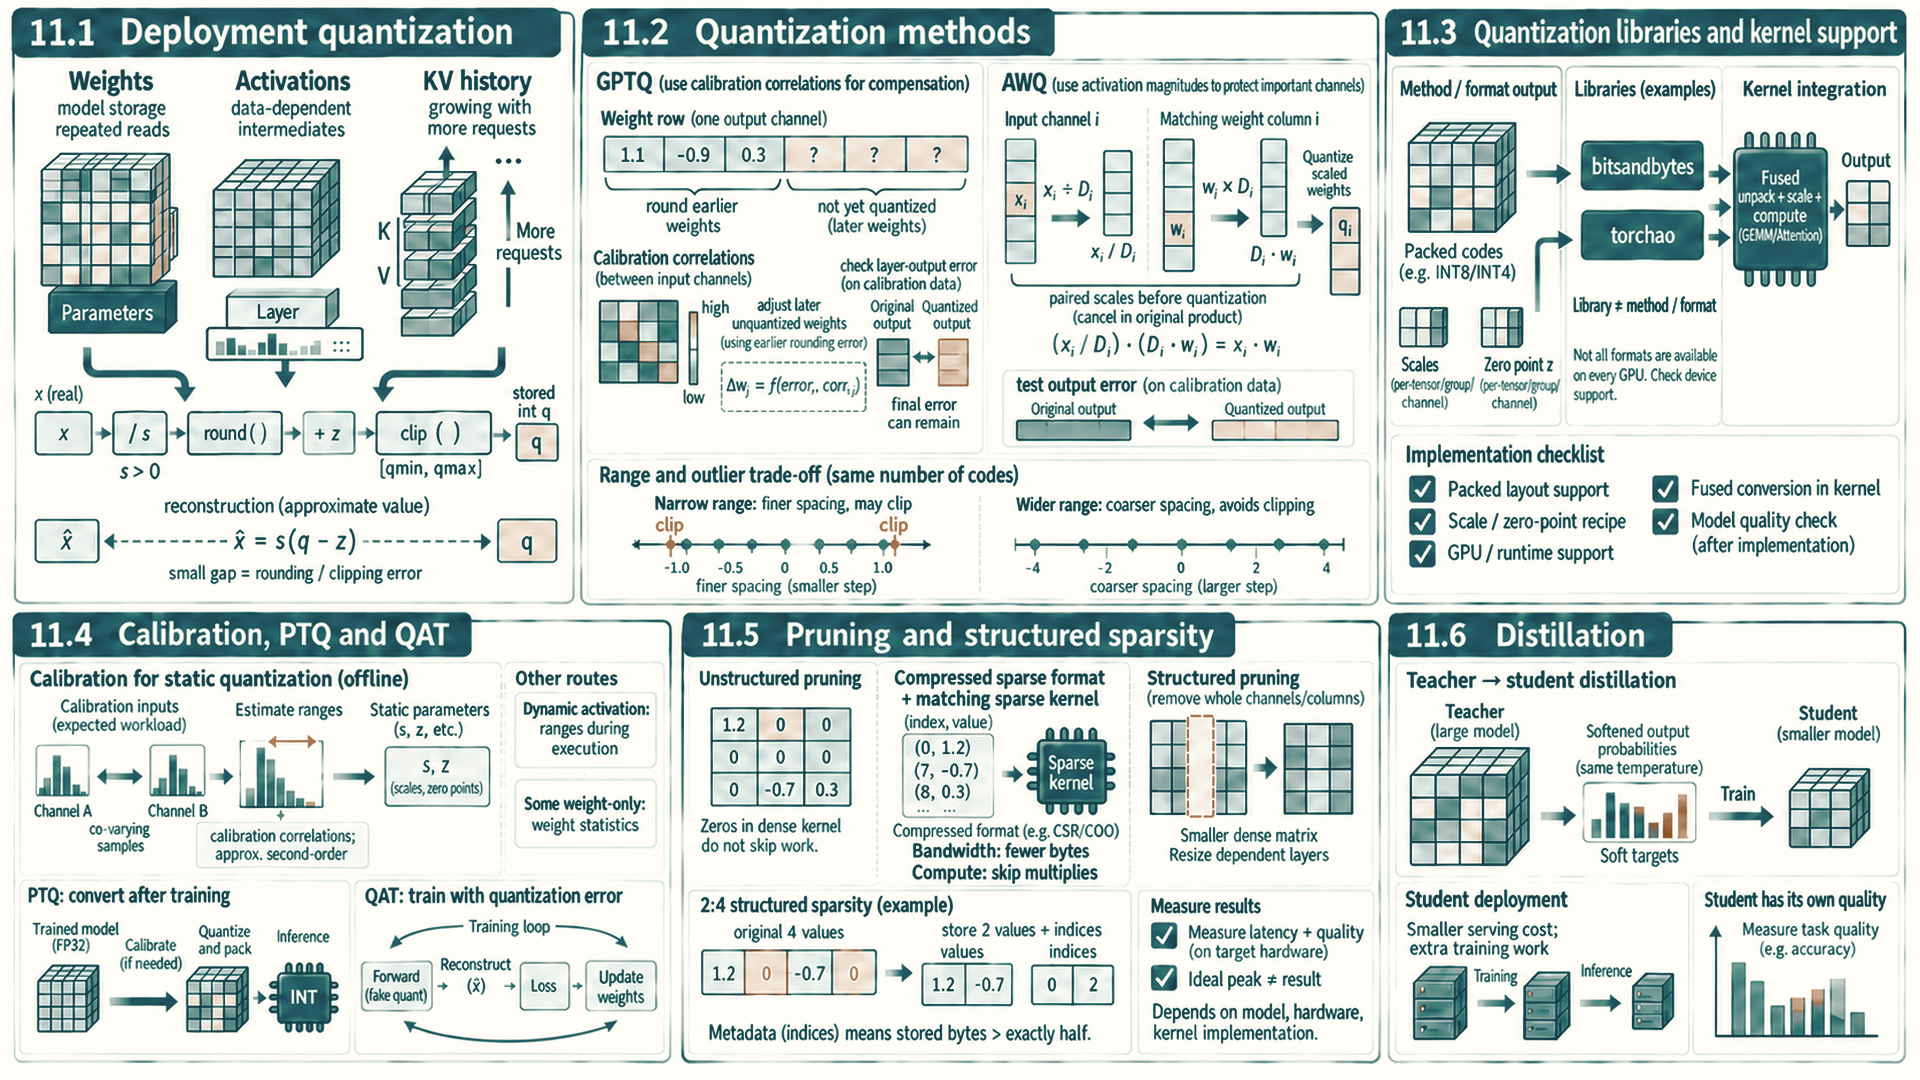
Section 10.4 and Section 10.6 estimated storage for model weights and the KV cache of active requests. Per-step traffic depends on which weights and cache entries the executed operations access and which reads reuse cached data. Section 6.2 showed why a small decode step can be limited by moving those bytes. Model compression reduces them. Its four families differ in what they change and in what they cost:
| Family | What changes | Main saving | Main cost | Section |
|---|---|---|---|---|
| Quantization | The number format of stored weights, activations, or KV cache | Fewer bytes per value | Rounding error, and the kernels must read the compact format | Section 11.1 to Section 11.4 |
| Pruning and sparsity | Selected weights become zero; whole structures can shrink dense tensors, while a sparse path can skip other zeros | Fewer bytes or multiplications when dense tensors shrink or sparse storage and kernels skip zeros | Accuracy loss, and a speedup only for supported sparsity patterns | Section 11.5 |
| Distillation | A smaller model is trained to imitate a larger one | Fewer parameters in total | A separate training run, and the result is a different model | Section 11.6 |
| Architectural reduction | The model is designed to store less state, as with grouped-query or sliding-window attention | A smaller KV cache | Requires a compatible architecture, training or adaptation | Section 10.6, Section 12.7 |
A smaller representation improves execution only when the runtime reduces the limiting work or memory traffic, or admits useful work that previously did not fit. Low-bit kernels may dequantize values inside the computation without materializing a full wider tensor. Expanding a compact checkpoint into full 16-bit tensors before each matrix multiplication can erase the traffic saving, so file size alone does not establish a speedup. Every family can change the model’s outputs, so each needs a quality check on the intended workload (Section 11.4).
11.1 Deployment quantization
Deployment quantization starts with an already-trained model and changes how selected tensors are represented at inference time. It is useful when the measured bottleneck is weight or cache bytes, memory capacity, or a hardware path that efficiently consumes the compact representation.
Weight quantization cuts persistent model bytes. Activation quantization changes intermediate tensors. KV-cache quantization cuts serving state that grows with requests and context. Scales and dequantization add work, so a smaller representation helps latency only when the selected kernels use it efficiently and quality remains acceptable.
- Weight quantization: Stores model parameters in fewer bits. It mainly targets persistent weight memory and repeated weight reads during inference.
- Activation quantization: Stores or computes intermediate tensors in lower precision. It can reduce traffic between operations, but it is more sensitive to calibration because activation distributions vary with data.
- KV-cache quantization: Stores attention keys and values in fewer bits during serving. It targets the dynamic memory object that grows with active requests and context length.
- Dequantization: Conversion from a compact representation back to a wider representation for computation. If dequantization is expensive or happens too early, the latency benefit can disappear.
- Scale metadata: Extra values that map low-precision integers or floating formats back to approximate real values. Group size and scale placement affect both quality and kernel cost.
Affine integer quantization stores an integer code \(q\) for a real value \(x\). The positive scale \(s\) sets the size of a quantization step. The integer zero point \(z\) is the code that represents the real value zero. Clipping limits the code to the target format’s range \([q_{\min},q_{\max}]\), for example \([-128,127]\) for a signed 8-bit integer. The runtime later reconstructs an approximate wider value when a kernel needs it:
\[ q = \text{clip}\left(\text{round}\left(\frac{x}{s}\right) + z, q_{min}, q_{max}\right) \tag{11.1}\]
\[ \text{dequantized } x = s \times (q - z) \tag{11.2}\]
Calibration chooses quantization parameters from tensors drawn from the expected workload.
- Calibration set: Prompts, activations, or layer inputs drawn from the expected workload and used to estimate value ranges.
The numerical trace in Section 11.4 follows observed values through scale selection, rounding, clipping, and reconstruction using these two mappings.
The stored code is smaller, but the end-to-end gain depends on where the second mapping occurs. A fused low-bit matrix kernel can unpack codes, apply scales, and accumulate without first materializing a full FP16 or BF16 tensor. A separate early dequantization pass can give back much of the saved memory traffic.
When a workload is memory-bound (Section 6.2), reducing bytes moved can be more valuable than reducing arithmetic. Evaluate whether the hot path avoids reading, writing, or transferring the wider representation.
11.2 Quantization methods
Weight-only quantization is usually the simplest inference path: it shrinks parameters while leaving activations in a higher precision. Activation quantization is more intrusive because activation distributions vary by layer, token, and workload. Key-value cache quantization targets long-context serving capacity and decode bandwidth, but it can affect attention quality and needs engine support.
- GPTQ: A post-training weight quantization algorithm that uses calibration inputs to limit the change in each layer’s output1. It is commonly used for low-bit inference checkpoints when compatible kernels exist.
- AWQ: Activation-aware Weight Quantization. It rescales input channels and their corresponding weight columns before low-bit weight quantization to reduce output error on the expected workload2. An input channel is one coordinate of a layer’s input vector. The matching weight column contains the weights that multiply that coordinate.
- FP8 and KV-cache quantization: FP8 targets lower-precision tensor and cache storage with hardware/runtime support. KV-cache quantization reduces long-context memory pressure but can introduce dequantization cost and attention-quality risk.
Both weight methods use layer inputs from calibration data, rather than judging each weight in isolation. Write those input vectors as the columns of \(X\), and the original weight matrix as \(W\). The original layer output is \(WX\). A reconstructed low-bit weight matrix \(\hat W\) should make \(\hat W X\) close to \(WX\) on those inputs.
GPTQ uses correlations between input channels to estimate how changes in weights affect this output error. This is the role of the paper’s second-order information. As weights are rounded in a chosen order, GPTQ adjusts weights not yet quantized to partly compensate for the rounding error already introduced.3
Example: Compensating for one rounded weight
Inputs: One calibration input is \(x=(1,1)\), and one output row has weights \((0.6,0.6)\). Its original output is \(0.6+0.6=1.2\). Assume the first weight is rounded to \(1\) while the second has not yet been quantized.
Intermediate change: Leaving the second weight at \(0.6\) would give \(1.6\). Reducing it to \(0.2\) restores \(1.2\) for this input.
Conclusion: An unquantized weight can compensate for an earlier rounding error. The second weight still needs quantization, so this intermediate correction does not promise zero final error. GPTQ uses many calibration inputs and their correlations, not this one-input adjustment rule.
AWQ instead searches for positive input-channel scale factors from calibration activations. Let \(D\) be a diagonal matrix containing those factors. Scaling weight columns to \(WD\) and inversely scaling the inputs gives \((WD)(D^{-1}x)=Wx\) before quantization. AWQ then quantizes the transformed weights and checks which factors reduce output error on the calibration data.4 This paired transform changes the effect of rounding. It does not keep all important weights in a wider format, and its channel factors are distinct from the integer reconstruction scales of Section 11.1.
Example: Why activation size matters to weight error
Inputs: For one output row, input channels have values \((10,1)\). Suppose quantization changes each corresponding weight by \(0.1\).
Output effect: The two weight errors contribute \(10\times0.1=1\) and \(1\times0.1=0.1\) to output error. Equal weight errors therefore matter differently on these inputs.
Conclusion: Calibration activations identify channels whose weight errors have a large output effect. AWQ tests channel scaling to reduce that effect on the workload. This calculation explains the motivation, not a complete AWQ scale-search procedure or a guaranteed quality improvement.
AWQ and GPTQ are method families, not runtime guarantees. Their checkpoints reduce weight bandwidth only through the kernel paths described in Section 11.3.
| Method | Mechanism | What it helps | What still must be checked |
|---|---|---|---|
| GPTQ | Uses calibration data and approximate second-order reconstruction to choose low-bit weights with lower layer-output error than naive rounding | Weight-only low-bit inference when parameter reads or model fit are the bottleneck | Quantization time, compatible kernels, quality on prompts from the expected workload, and whether dequantization stays fused |
| AWQ | Uses calibration activations from the expected workload to find important channels and protects them through activation-aware scaling before low-bit weight quantization | Hardware-friendly weight-only inference where a small set of important channels drives error | Calibration domain, packed-weight layout, kernel support, and whether activation outliers shift in production |
| FP8 path | Stores or computes selected tensors in FP8 with scaling factors and wider accumulation where required | Bandwidth, tensor-core throughput, activation or KV-cache footprint on supported accelerators | Scaling granularity, amax handling, supported operations, and numerical quality |
11.3 Quantization libraries and kernel support
A quantization method becomes a runnable performance path through a library and compatible kernels.
bitsandbytes: A low-precision training and inference library with quantized optimizer and weight paths5. Its benefit depends on the selected model, format, GPU, and kernel support.torchao: PyTorch-native quantization and sparsity tooling that integrates supported low-precision representations with PyTorch models and execution paths6.- Implementation support: The concrete combination of packed layout, scale granularity, dequantization strategy, matrix kernel, GPU architecture, and runtime version that turns a small checkpoint into a fast execution path.
- Measurements: Checkpoint size demonstrates storage compression. End-to-end latency, throughput, peak memory, and quality demonstrate whether the implementation helps the workload.
Library names serve as implementation examples rather than definitions of quantization. GPTQ, AWQ, FP8, INT8, and INT4 describe methods or formats. Bitsandbytes and torchao provide selected software paths for them.
11.4 Calibration, PTQ and QAT
Hardware support determines whether the GPU and runtime have fast kernels for the chosen format. Offline calibration is needed by static activation quantization and methods such as GPTQ or AWQ. Dynamic activation quantization derives ranges during execution, and some weight-only methods use weight statistics without a separate workload calibration run7.
- Scale: A multiplier that maps low-precision stored values back to approximate real values. Scales can be per tensor, per channel, per group, or more specialized depending on the method.
- Clipping range: A selected numeric range that limits outliers before quantization. Aggressive clipping can improve average reconstruction but harm rare important values.
- Per-channel or per-group quantization: Uses separate scales for smaller tensor groups. This usually improves quality relative to one global scale, but increases metadata and kernel complexity.
- Weight-only calibration: Focuses on parameter tensors and workload-derived activations used by methods such as GPTQ or AWQ.
- Activation and KV-cache calibration: Targets runtime tensors whose distributions depend on prompts, sequence length, layer, and model behavior. Mistakes here can produce quality loss that a simple file-size check does not reveal.
Two deployment paths differ in when low-precision behavior enters the model lifecycle. The third entry is the gradient approximation that the second path depends on:
- Post-Training Quantization (PTQ): Converts an already-trained model for lower-precision deployment. For a calibrated static path, a run records weight or activation ranges from the expected workload, derives scales and zero points, and packs the selected tensors. Dynamic and weight-only paths can obtain their parameters differently. All paths need quality and runtime checks.
- Quantization-Aware Training (QAT): Trains with fake quantization and dequantization operations in the forward pass, so model updates see an approximation of the error introduced by the deployed representation.
- Straight-Through Estimator (STE): A backward-pass approximation used for a rounding-like fake-quantization operation. It substitutes a usable derivative estimate so gradient-based optimization can continue.
Example: From calibration values to integer codes
Inputs and policy: A toy inference activation tensor supplies calibration values \([-2,-0.6,0,1.4,5]\). To expose the arithmetic, allow just eight integer codes, \(q_{\min}=0\) through \(q_{\max}=7\). This is a teaching code range, not a claim about a deployed three-bit kernel. Apply the affine min/max policy documented by PyTorch’s MinMaxObserver: \(s=(x_{\max}-x_{\min})/(q_{\max}-q_{\min})\) and \(z=q_{\min}-\operatorname{round}(x_{\min}/s)\)8. The observed interval already includes zero. Round to nearest, with halfway ties going to the even integer, then clip the code to \([0,7]\) and reconstruct \(\hat x=s(q-z)\)9.
Calibration: The observed minimum is \(-2\) and maximum is \(5\), so \(s=(5-(-2))/(7-0)=1\) and \(z=0-\operatorname{round}(-2/1)=2\). Zero therefore receives code \(2\). The last row below adds a later value of \(12\) while keeping the calibrated scale fixed. Signed error means \(\hat x-x\).
| Input \(x\) | \(x/s\) | Rounded value plus \(z\) | Clipped code \(q\) | Reconstruction \(\hat x\) | Error |
|---|---|---|---|---|---|
| \(-2\) | \(-2\) | \(0\) | \(0\) | \(-2\) | \(0\) |
| \(-0.6\) | \(-0.6\) | \(1\) | \(1\) | \(-1\) | \(-0.4\) |
| \(0\) | \(0\) | \(2\) | \(2\) | \(0\) | \(0\) |
| \(1.4\) | \(1.4\) | \(3\) | \(3\) | \(1\) | \(-0.4\) |
| \(5\) | \(5\) | \(7\) | \(7\) | \(5\) | \(0\) |
| \(12\) | \(12\) | \(14\) | \(7\) | \(5\) | \(-7\) |
Outlier trade-off: Recalibrating with \(12\) included expands the interval to \([-2,12]\), giving \(s=14/7=2\) and \(z=0-\operatorname{round}(-1)=1\). The outlier now reconstructs exactly: code \(7\) gives \(2(7-1)=12\). But \(-0.6\) now reconstructs as \(0\) and \(1.4\) as \(2\), with errors \(+0.6\) in both cases. The former endpoint \(5\) maps through \(5/2=2.5\), rounded to \(2\), to code \(3\) and reconstruction \(4\). Accommodating the outlier doubled the step size for every value sharing this scale.
Conclusion: Keeping the original range preserves finer spacing but clips the outlier. Expanding it protects the outlier while increasing some smaller-value errors. Separate groups can fit different ranges at the cost of more scale metadata and kernel work. These arithmetic errors do not determine task quality by themselves. This example implements neither GPTQ nor AWQ, FP8 scaling, or every PTQ calibration recipe.
During QAT, the forward pass applies \(\operatorname{fake\_quant}(x)\), a simulation of the chosen deployment quantization. Rounding has zero derivative between its jumps and is not differentiable at the jumps, so its true derivative cannot provide the usual learning signal. A clipped STE instead passes the incoming gradient through inside a chosen representable interval and blocks it outside. For the affine mapping above, use \(x_{\min}=s(q_{\min}-z)\) and \(x_{\max}=s(q_{\max}-z)\). The following is a backward approximation, not the true derivative of quantization. Implementations may differ at the clipping boundaries:
\[ \text{STE backward rule: } \frac{\partial \text{fake-quant}(x)}{\partial x} = 1 \text{ if } x \in [x_{min}, x_{max}] \text{ else } 0 \tag{11.3}\]
Here ∂ fake_quant(x) / ∂x means the rate of change assigned to the fake-quantization operator with respect to its input x. The equality defines the surrogate gradient used by backward propagation. It does not claim that the true derivative of rounding is one.
Calibrated PTQ adds an offline calibration step and may lose quality at low bit widths. QAT spends training compute to adapt the model to the deployed representation. Compare quality on requests drawn from the expected workload, then measure whether the selected engine uses the packed format in its hot kernels.
Quality is measured on the task, not on the tensors. Three checks are common, and each detects a different kind of damage. Perplexity (the exponential of the average per-token cross-entropy loss on held-out text, where lower is better) detects broad damage to the model’s predictions cheaply. Task accuracy on a fixed evaluation set, such as a public benchmark or a sample of production prompts with reference answers, detects damage that a small perplexity change can hide. A side-by-side comparison with the uncompressed model on the same prompts under greedy decoding shows how often, and where, the generated tokens diverge. The comparison holds prompts, tokenizer, and decoding settings fixed. It also records hardware, runtime, batch, and kernel choices, and repeats the uncompressed run to check execution variation. Differences beyond that variation are evidence of a change from the compressed execution path. Any change in kernel arithmetic is reported alongside the representation change.
Group size is the number of values that share one quantization scale. A smaller group allows separate scales to fit local values, but adds scale metadata and indexing work. It does not guarantee lower tensor error or better task quality: calibration, rounding, and the selected group size still need comparison on the workload.
| Group-size choice | Quality effect | Runtime effect | When it is attractive |
|---|---|---|---|
| Small groups | Can improve local reconstruction when separate scales better fit the values. The result depends on calibration and rounding. | More scale reads, more metadata, and more complex packing or dequantization | Accuracy is fragile and kernels are designed for that grouping |
| Large groups | More values share a scale, so outliers can waste quantization range | Less metadata and simpler memory access | Bandwidth or metadata overhead dominates and quality remains acceptable |
| Per-channel groups | Fits channel-level activation or weight ranges | Works well when kernels can load scales along the channel dimension efficiently | Linear layers where channel statistics are stable enough under calibration |
| Per-block groups | Fits local blocks rather than whole tensors | Can align with tile layouts, but only if the backend expects that layout | FP8 or INT4 paths with block-scaled kernels |
Poor calibration can preserve speed while harming quality. Poor hardware or kernel support can preserve quality while failing to improve latency.
11.5 Pruning and structured sparsity
Quantization keeps every weight but stores it in fewer bits. Pruning instead sets chosen weights to zero. Savings require either smaller dense tensors after whole structures are removed, or a sparse format and matching kernel that skip the zeros. Whether the zeros save time depends on where they fall, because GPU matrix kernels process regular tiles and gain nothing from zeros they cannot skip.
- Unstructured sparsity: any individual weights may be zero. It allows more freedom to choose which weights to remove than a fixed structured pattern, but accuracy depends on the pruning method and model. Dense GPU kernels cannot skip scattered zeros. The saving then requires a compressed storage format and specialized sparse kernels.
- Structured sparsity: whole rows, columns, attention heads, or blocks are removed. Removing complete channels or heads can produce smaller dense matrices after dependent tensors are resized. Removing isolated blocks instead needs a compatible block-sparse kernel. The quality cost depends on which structures are removed and any later adaptation.
- Semi-structured 2:4 sparsity: in every group of four consecutive weights, at most two are nonzero. The compressed format stores the two kept values plus a 2-bit position index for each. Supported 2:4 Sparse Tensor Core operations on the cited Ampere design can offer up to twice the corresponding dense arithmetic peak.10 Later devices, dtypes, kernel shapes, and actual latency need their own check.
Retraining a model with billions of parameters after pruning is expensive, so the methods below prune once, after training. SparseGPT prunes GPT-family models to at least 50 percent unstructured sparsity in one pass without retraining, reaches 60 percent on its largest models with a small perplexity increase, and extends to 2:4 and 4:8 patterns.11 Wanda removes the weights with the smallest magnitude multiplied by the L2 norm of the corresponding input feature across calibration tokens, comparing weights within each output row, also without retraining or weight updates, and is evaluated for unstructured, 4:8, and 2:4 sparsity.12
For the illustrative 4,096-by-4,096 BF16 projection, 2:4 storage including position metadata is about 18.9 MB, or 56 percent of the dense bytes. The ideal bandwidth floor improves by about 1.8 times. Supported sparse math has an ideal two-times peak. Neither ratio predicts latency, and quality after pruning must be measured.
Example: What 2:4 sparsity saves in one projection
Inputs: The \(4{,}096\times4{,}096\) BF16 projection of Section 6.2, whose dense weights occupy \(2\times16{,}777{,}216=33{,}554{,}432\) bytes, is pruned to the 2:4 pattern.
Storage: Half the weights remain: \(8{,}388{,}608\) values at 2 bytes, or \(16{,}777{,}216\) bytes. Each kept value adds 2 bits of position metadata, \(8{,}388{,}608\times2/8=2{,}097{,}152\) bytes. The total is \(18{,}874{,}368\) bytes, 56 percent of the dense size.
Time: For one row, the bandwidth-only model gives a time floor of about \(18.9\text{ MB}/3.35\text{ TB/s}\approx5.6\) microseconds instead of 10.0, a 1.8-times ratio between these ideal floors. For a large batch that saturates compatible Sparse Tensor Cores, the doubled math peak permits an ideal 2-times arithmetic gain. Neither ratio predicts measured latency, which also includes kernel efficiency and overhead.
Conclusion: In the memory-bound regime 2:4 sparsity helps the way quantization does, by moving fewer bytes. In the compute-bound regime it helps by skipping multiplications. Both gains require a kernel that reads the 2:4 format, and both come after half of the weights have been removed, so model quality must be measured as in Section 11.4.
11.6 Distillation
Quantization and pruning shrink an existing model. Knowledge distillation trains a different, smaller one. A small student model is trained to reproduce the output distribution of a larger teacher model. Hinton et al. train on the teacher’s class probabilities, softened by raising the softmax temperature, as soft targets, and use the same temperature for the student.13 For a language model the targets are the teacher’s next-token distributions at each position, which carry more information per example than the single correct token.
The student’s serving cost follows its own size. Using model size as a rough count of participating dense-projection weights (Section 6.6), an 8B student of a 70B teacher needs about \(2\times8\times10^9=16\) GFLOP per generated token instead of 140 GFLOP. BF16 storage for 8 billion and 70 billion parameters is 16 GB and 140 GB. If a simplified decode model assumes one HBM read of each byte budget per step, the student’s modeled weight traffic is lower by a factor of 8.75. Actual traffic depends on the tensors accessed and their cache reuse. When teacher distributions are computed on demand during student training, each training token needs a teacher forward pass (\(2\times70\times10^9=140\) GFLOP) as well as the student’s forward and backward passes (\(6\times8\times10^9=48\) GFLOP), about 3.9 times the arithmetic of training the student alone on the same tokens. Precomputing teacher targets can amortize repeated teacher passes, at the cost of storing and reading those targets. These estimates count dense parameter arithmetic and omit attention-score work and runtime overhead.
Unlike quantization, distillation cannot be adjusted at deployment time. The student is a new model with its own quality profile, so it is evaluated on the target tasks like any other model. A distilled student can also serve as the draft model for speculative decoding (Section 14.1), where its agreement with the teacher sets the acceptance rate.
The weight and KV estimates in Chapter 10 describe the memory a planned request set needs; the compression methods here can reduce parts of that total. These estimates do not determine where each request’s state is placed or how attention kernels find it. Chapter 12 follows that layout: token order stays logical while physical blocks are allocated, reused and read at different addresses.
References
Frantar, E., Ashkboos, S., Hoefler, T., & Alistarh, D. (2023). GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers. arXiv:2210.17323. GPTQ paper. Supports one shot post-training quantization with approximate second-order reconstruction to 3 to 4 bits, with speedups from reduced memory movement. Limit: the paper focuses on weight only generative inference and states no computational reduction and no activation quantization.↩︎
Lin, J., et al. (2024). AWQ: Activation-aware Weight Quantization for On-Device LLM Compression and Acceleration. In Proceedings of MLSys 2024. arXiv:2306.00978. AWQ paper. Supports selecting salient weight channels from activation magnitude and protecting them with per-channel scaling fitted on calibration activations, without backpropagation. Limit: the gain needs a compatible 4-bit packing and fused kernel path; checkpoint size alone does not prove latency improvement.↩︎
Frantar, E., Ashkboos, S., Hoefler, T., & Alistarh, D. (2023). GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers. arXiv:2210.17323. GPTQ paper. Supports one shot post-training quantization with approximate second-order reconstruction to 3 to 4 bits, with speedups from reduced memory movement. Limit: the paper focuses on weight only generative inference and states no computational reduction and no activation quantization.↩︎
Lin, J., et al. (2024). AWQ: Activation-aware Weight Quantization for On-Device LLM Compression and Acceleration. In Proceedings of MLSys 2024. arXiv:2306.00978. AWQ paper. Supports selecting salient weight channels from activation magnitude and protecting them with per-channel scaling fitted on calibration activations, without backpropagation. Limit: the gain needs a compatible 4-bit packing and fused kernel path; checkpoint size alone does not prove latency improvement.↩︎
bitsandbytes-foundation. (n.d.). bitsandbytes README. bitsandbytes README. Supports three versioned paths: 8-bit optimizers with block-wise quantization, LLM.int8 with vector-wise quantization plus 16-bit outlier handling, and QLoRA 4-bit with frozen base plus trainable LoRA adapters, with primitives through Linear8bitLt, Linear4bit, and the optim module. Limit: Python 3.10 plus PyTorch 2.4 plus accelerator support tables vary by release; the chapter keeps benefit claims conditional on the installed combination.↩︎
PyTorch. (torchao stable documentation, created Mar 25, 2026). Welcome to the torchao Documentation. torchao documentation. Supports torchao as PyTorch-native quantization and sparsity tooling where quantize_ converts linear module weights in place under a config such as Int4WeightOnlyConfig, with kernel and packing choices that differ by device. Limit: configs, packing formats, and the version compatibility table change by release; consult the installed torchao reference before assuming a path exists.↩︎
Subramanian, S., Saroufim, M., & Zhang, J. (2022). Practical Quantization in PyTorch. PyTorch. Practical Quantization in PyTorch. Distinguishes static calibration from dynamic activation quantization and weight-only paths. Its API examples and backend support describe the publication period, not current deployment compatibility.↩︎
PyTorch. (2.14 documentation). MinMaxObserver. PyTorch MinMaxObserver documentation. Supports affine scale and zero-point selection from observed extrema. Limit: the example’s eight-code interval is a teaching choice; it does not establish a packed three-bit deployment path or an optimal calibration range.↩︎
PyTorch. (2.14 documentation). torch.fake_quantize_per_tensor_affine. PyTorch affine fake-quantization documentation. Documents rounding, clipping to the integer interval, and reconstruction with scale and zero point. Limit: fake quantization returns floating-point values and does not demonstrate packed storage or faster inference. The worked calculation explicitly uses nearest-even rounding.↩︎
Mishra, A., Albericio Latorre, J., Pool, J., Stosic, D., Stosic, D., Venkatesh, G., Yu, C., & Micikevicius, P. (2021). Accelerating Sparse Deep Neural Networks. arXiv:2104.08378. Supports the 2:4 pattern with two nonzero values stored per group of four, 2-bit metadata per nonzero value, and Sparse Tensor Cores on the NVIDIA Ampere architecture with twice the math throughput of dense matrix units. Limit: end-to-end gains depend on the share of time in sparse matrix multiplications and on accuracy recovery, which the worked example does not measure.↩︎
Frantar, E., & Alistarh, D. (2023). SparseGPT: Massive Language Models Can be Accurately Pruned in One-Shot. ICML 2023. arXiv:2301.00774. Supports one-shot pruning of GPT-family models to at least 50 percent sparsity without retraining, 60 percent unstructured sparsity on OPT-175B and BLOOM-176B with negligible perplexity increase, and generalization to 2:4 and 4:8 patterns. Limit: speedups require kernels for the chosen sparsity pattern.↩︎
Sun, M., Liu, Z., Bair, A., & Kolter, J. Z. (2024). A Simple and Effective Pruning Approach for Large Language Models. ICLR 2024. arXiv:2306.11695. Supports Wanda’s criterion of weight magnitude multiplied by the input feature’s L2 norm across calibration tokens, applied per output row without retraining or weight update, evaluated for unstructured, 4:8, and 2:4 sparsity. Limit: reported quality depends on model family and sparsity level.↩︎
Hinton, G., Vinyals, O., & Dean, J. (2015). Distilling the Knowledge in a Neural Network. arXiv:1503.02531. Supports training a small model on the class probabilities of a larger model as soft targets, produced by raising the softmax temperature, with the same temperature used for the small model. Limit: the paper studies classification and speech models. Section 11.6 applies distillation to next-token prediction and derives the illustrative cost estimates.↩︎