5 Triton and attention kernels
GPU kernels assign tensor work to many parallel program instances. A custom kernel makes that assignment explicit: it chooses which tile each instance reads, how boundary elements are masked, which values stay on chip, and where the result is stored. These choices can reduce memory traffic or expose more parallel work when an existing operation does not fit the workload.
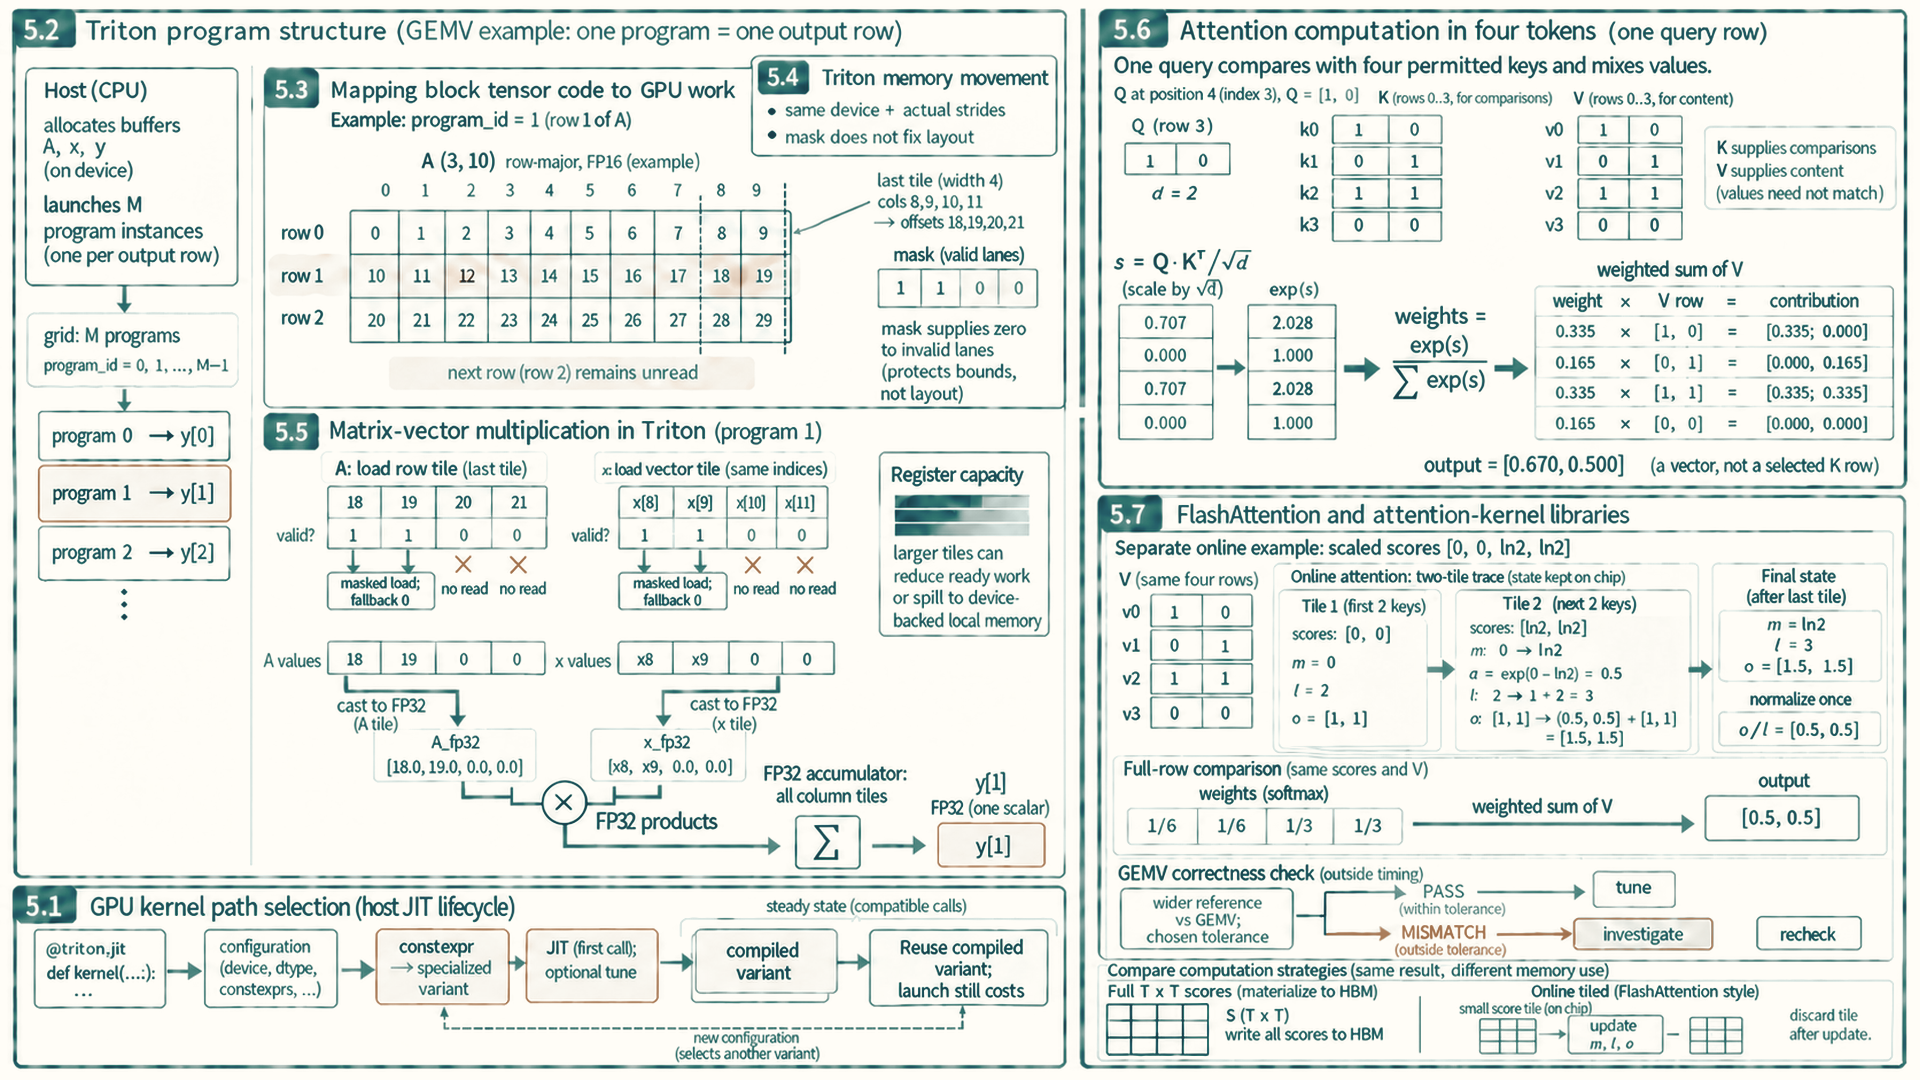
Triton is a Python-based language and compiler for writing GPU kernels at a block-tensor level. Its main abstraction is a program instance that handles a tile of data and is lowered into GPU code. This tile-centered language and compiler design follows Triton: An Intermediate Language and Compiler for Tiled Neural Network Computations1.
Triton is useful when the hot operation is regular, the library kernel does not match the needed layout, or fusion can remove intermediate HBM traffic. Vendor GEMM kernels remain the usual baseline for standard matrix work, while distributed communication and request scheduling belong to their own software layers.
A Triton kernel still obeys GPU constraints. Program IDs map to tiles. Block sizes shape parallelism and register pressure. Masks protect boundary loads. Strides define physical memory layout. Loads and stores still need coalescing and locality.
The host launcher submits the matrix-vector kernel with a one-dimensional grid containing one program instance for each matrix row.
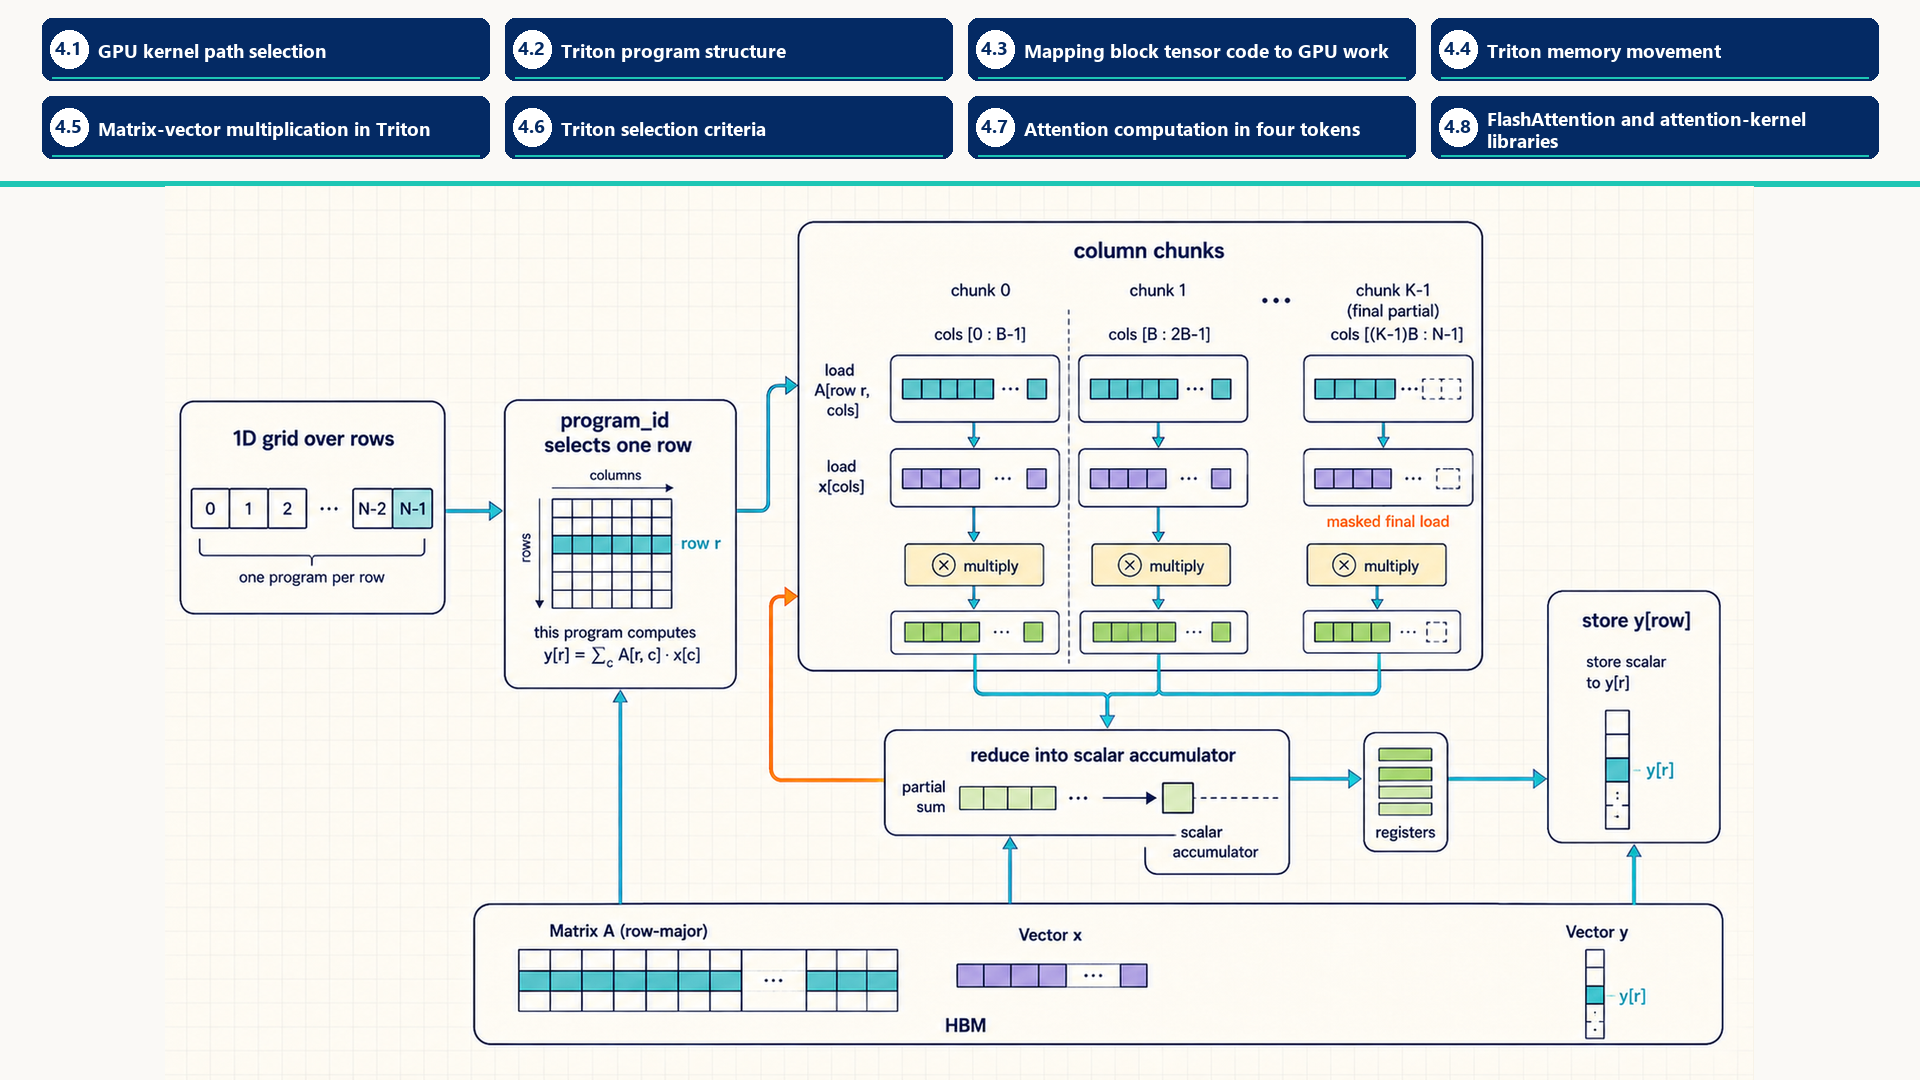
A program selects its row, walks through column chunks, masks only the final partial load, multiplies matching matrix and vector values, and reduces them into one scalar accumulator before one scalar store. Triton chooses lower-level thread and instruction mapping during compilation. Generated code and profiling are needed to confirm the resulting hardware behavior.
The changes this chapter develops are to move fewer bytes, because fusion and tiling keep intermediate values on chip, and to keep the hardware busy, because block size affects how much parallel work reaches the SMs. The trace interpretation section brings these mechanisms together with the other bottleneck classes after the kernel mechanisms are in place.
A Triton kernel defines the addresses and arithmetic of one tensor operation. Changing the kernel can affect end-to-end latency and memory use, while serving and distributed software still control admission, cache allocation and communication policy.
5.1 GPU kernel path selection
A PyTorch expression, a Triton kernel, and a CUDA C++ kernel reach GPU work through distinct roles. PyTorch expresses model operations. A compiler can transform those operations. Triton and CUDA C++ provide alternative source languages for a custom kernel. CUDA runtime or driver APIs submit the resulting work to the GPU.
Kernel implementations differ by who writes them and where an engineer can make a useful change. The source form determines whether the first change belongs in custom kernel code, the captured graph, a library call, or the runtime launch sequence.
This four-way classification locates the layer where a performance change belongs:
- Hand-written Triton: A performance engineer or library author changes tile shape, masks, strides, reductions, launch grid, or autotuning. Autotuning benchmarks candidate kernel configurations and selects one for the target workload; it is optional. The result is a compiled GPU kernel launched through CUDA.
- Compiler-generated Triton: TorchInductor or another compiler backend produces the kernel. The useful inputs to change are the source graph, dimensions, layout, fusion legality, and compiler settings.
- CUDA C++ extension: A performance engineer or library author changes threads, blocks, shared memory, synchronization, and CUDA C++ integration. The result is a compiled GPU kernel.
- Vendor library kernel: A vendor supplies the prebuilt kernel. The application changes the API choice, dimensions, dtype, layout, and supported backend path rather than the kernel source.
A workload can launch all four forms over the same GPU tensors. The composition point is the framework graph or host launch sequence. A Triton source function does not inline arbitrary CUDA C++ or vendor-library kernel source.
A manually written @triton.jit kernel is lowered through Triton intermediate representations and LLVM compiler tools toward NVIDIA Parallel Thread Execution (PTX) code. LLVM supplies reusable code optimization and generation components.
PTX is an intermediate instruction-set representation, not the final device instruction stream. The NVIDIA driver still compiles or loads executable device code. This is the Triton kernel path, not the full PyTorch compiler stack.
The lowering path changes who controls each optimization, but every route still produces GPU code that CUDA submits and executes. A hand-written Triton kernel exposes that work as program instances, offsets, masks, loads, reductions, and stores.
5.2 Triton program structure
A Triton program has a host-side launch and a device-side tile program. Just-in-time (JIT) compilation compiles the decorated function when it is first needed for a particular device and configuration. Python code allocates tensors, chooses the launch grid, and calls that compiled function. The Triton program instance then uses its program ID to decide which tile of memory it handles.
The launch grid creates Triton program instances, and each program ID chooses a tile. Offsets choose elements within that tile, while masks prevent out-of-bounds access. Loads read valid values from GPU memory, reductions combine values, and stores write results. JIT compilation specializes the program for a device and configuration.
@triton.jit: Marks a Python function for Triton compilation.- Program instance: One logical tile of work selected by the launch grid.
tl.program_id: Identifies which tile the current program instance handles.tl.arangeand offsets: Create vectorized positions inside the tile.- Block pointers and strides: Describe tiled memory regions, physical layout, and boundary behavior.
- Masks: Prevent out-of-bounds loads and stores on partial tiles.
tl.loadandtl.store: Move values between GPU memory and registers.- Reductions: Operations such as
tl.sumcombine values inside the tile.
Those primitives describe the body of one program instance. Compilation adds a second set of concerns: when variants are created, which values are fixed at compile time, and whether the selected tile uses too many registers.
Changes in device, dtype, compile-time constants, or tile size can produce new compiled variants. Larger tiles may improve reuse but consume more registers and leave room for fewer active programs. When temporary values exceed available registers, they can spill to CUDA local memory, often backed by device memory, adding traffic and stalls.
- JIT compilation: Triton compiles the decorated function when it is called for a particular device, dtype, and compile-time configuration. The first call can include compilation and autotuning overhead, so timing should separate warmup from steady state.
tl.constexpr: A compile-time parameter. Values such as tile size, loop bounds, or boolean feature flags can specialize generated code rather than being loaded as ordinary runtime tensor values.- Specialization: The compiler can generate different code for different constexpr values, shapes, strides, or selected autotune configurations. This is why one Triton function can produce several compiled kernel variants.
- Register pressure: Large tiles, many temporaries, or unrolled loops can consume too many registers per program instance. More registers can reduce occupancy or spill temporary values to CUDA local memory, a per-thread address space commonly backed by device memory rather than on-chip storage.
- Spilling: When values that should have stayed in registers are placed in CUDA local memory because register demand is too high. In profiler output, spilling often appears as unexpected device-memory traffic and stalls.
A useful reading order is launch grid first, then program ID, then offsets, then loads, arithmetic, and stores. If performance is poor, inspect whether offsets are coalesced, masks are excessive, the tile is too small or too large, and the generated reduction incurs register spilling or unnecessary memory traffic.
5.3 Mapping block tensor code to GPU work
Mapping means assigning each Triton program instance to a tile of output data and then translating tile-relative positions into physical memory addresses. This is the bridge between readable block-tensor code and real GPU loads, arithmetic, and stores.
Triton code is written as if each program operates on vectors or blocks. The compiler turns that block program into GPU instructions. PyTorch usually allocates input and output tensors before the kernel runs. The Triton kernel reads and writes those buffers.
Good Triton kernels use tile sizes that expose enough parallelism without excessive register pressure. They keep hot values in registers, use masks only where necessary, and choose memory strides so adjacent lanes read adjacent data. Autotuning can search tile parameters, but the benchmark must match the real workload.
Example: Addresses and a partial tile: Take a contiguous row-major matrix A with shape (3, 10) and a tile width of 4. Using zero-based indices, program instance 1 handles row 1, the second row. Its final tile has column positions [8, 9, 10, 11], giving element offsets 1 * 10 + cols = [18, 19, 20, 21] from the start of A.
The mask cols < 10 is [True, True, False, False]. A masked tl.load with other=0 reads only offsets 18 and 19 and supplies zero for the other two positions. Columns 10 and 11 are outside this row; masking them prevents the tile from reading values belonging to the next row. This address calculation assumes the stated contiguous layout. A different layout needs its actual strides.
5.4 Triton memory movement
A Triton program controls memory movement inside one GPU kernel. It uses the same registers, on-chip storage, caches, L2, and HBM as a CUDA C++ kernel, while expressing the address calculation and tile schedule through Triton operations.
Moving tiled data: The first memory decision is which addresses each program instance touches. Loads and stores become efficient when adjacent lanes access adjacent useful data, masks cover only true boundaries, and block pointers describe the physical layout without unnecessary materialization.
tl.load: Reads elements from GPU memory into values used by the program instance. Pointer arithmetic, dimensions, masks, and cache options determine the resulting transactions.tl.store: Writes program results to GPU memory. Output layout and masks determine whether stores are contiguous and whether partial tiles waste traffic.- Mask: A lane-level validity condition for partial tiles or irregular boundaries. Correct masking protects memory safety. Excessive masking can reduce useful work.
- Block pointer: A structured description of a tiled memory region, including dimensions, strides, offsets, block dimensions, and boundary behavior.
- Program order: The mapping from program IDs to tiles. Reordering tile visits can increase L2 reuse without changing the mathematical result.
Cache and tile-order hints: Triton memory operations can express supported cache and eviction intent, while tile order creates the structural reuse that makes cache useful. Measurement should establish the reuse pattern before a hint is treated as an optimization.
- Cache modifier: A
tl.loadortl.storeoption that requests supported lower-level cache behavior, such as cache-all, L2-oriented, streaming, or write-through behavior depending on the operation and backend. - Eviction policy: A replacement preference such as evict-first or evict-last where supported. It guides replacement behavior and does not guarantee residency.
- Grouped tile order: A program-ID mapping that visits related output tiles close together so they can reuse matrix or activation data through L2.
- Autotuned configuration: A compile-time choice of tile dimensions and of the
num_warpsandnum_stagesvalues, measured for the target range of tensor dimensions. In Triton,num_warpssets how many warps cooperate on one program instance, andnum_stagessets how many stages the compiler uses when software-pipelining a loop.2
One word, three meanings: stage
Software-pipelining stage: num_stages selects the compiler’s requested software pipeline depth for eligible loops. The compiler may prepare a later iteration’s data while computing an earlier iteration. The resulting loads and overlap depend on the loop, backend, and GPU. This setting belongs inside one kernel and is not a measured count of outstanding memory requests.
Pipeline-parallel stage: a contiguous range of model layers. In plain pipeline parallelism, one device runs a stage (Section 20.1). With tensor parallelism, a group of devices shares that stage’s layer computations (Section 20.3).
ZeRO stage: a numbered level of state sharding, where stage 1 shards optimizer state, stage 2 adds gradients, and stage 3 adds parameters (Section 18.4.2). The number names how much is sharded, not a position in time.
Tiled movement first needs correct offsets, strides and masks. Tile dimensions and program order interact with memory traffic and register use, so measurements guide which to test. Cache hints address evidenced reuse or replacement behavior; they cannot repair unnecessary memory requests. The next comparison separates memory operations inside the kernel from transfers and allocation controlled by the host runtime.
CUDA and Triton responsibility map: The comparison below assigns each memory problem to the runtime or kernel layer that can change it. This prevents a host-transfer problem from being treated as tile code and prevents a coalescing problem from being treated as a runtime flag.
| Memory issue | CUDA/runtime responsibility | Triton/kernel responsibility | First diagnostic |
|---|---|---|---|
| Host-device copy | Placement calls, pinned buffers, copy APIs, streams, and copy engines | Outside the Triton kernel body | Timeline copy spans and synchronization |
| Kernel HBM traffic | Selected CUDA, vendor, or generated kernel path | tl.load/tl.store addresses, masks, block pointers, and tile dimensions |
Bytes moved, sectors, and useful bandwidth |
| Coalescing and stride | CUDA thread indexing, layout, vector loads, or staging | Strides, offsets, tl.arange, masks, and block layout |
Transactions per useful byte |
| L2 reuse | Launch order, sequencing, and supported persistence controls | Program-ID mapping, grouped ordering, and tile reuse | Reuse distance and L2 traffic |
| Peer or collective movement | CUDA peer access and communication backends | Outside an ordinary single-GPU Triton kernel | Topology, transport logs, and transfer spans |
5.5 Matrix-vector multiplication in Triton
The following Triton matrix-vector multiplication (GEMV) kernel grounds the program structure in concrete code. GEMV is useful as an example because it exposes the memory-access questions that custom kernels often need to answer: which program instance owns each output element, whether adjacent lanes read adjacent memory, how partial tiles are masked, and where the reduction lives.
In matrix-vector multiplication y = Ax, each program instance computes one element of the output vector y, corresponding to one row of the matrix A. The kernel loads elements of the matrix row and the vector x in blocks, multiplies them, and reduces the products. The point is not that every GEMV should be custom-written. The point is that this small kernel makes tile assignment, global-memory addresses, masks, reductions, and stores visible. tl.load reads values from device addresses into the program. Caches may satisfy some requests, so profiler counters are needed to measure L1, L2, and HBM traffic. tl.store writes the output through the device memory hierarchy.
One program computes one output row by reading a contiguous row of A and the matching vector elements, accumulating in FP32, then storing one scalar. This example assumes row-major contiguous FP16 inputs and a separate FP32 output on one device. A transposed view needs explicit strides or a measured copy.
Example: Triton matrix-vector kernel
One program instance computes one output row. It walks across columns in BLOCK-sized chunks, masks the final partial chunk, accumulates products in FP32, and stores one scalar. The launcher supplies an M-program grid. Production integration includes correctness tests and block-size tuning.
Input contract: A is a contiguous row-major FP16 CUDA tensor of shape (M, N) with element strides (N, 1). x is a contiguous FP16 vector of length N, and y is a separate contiguous FP32 output vector of length M, all on the same device. Thus A[row, col] lives at A + row * N + col, while x[col] and y[row] use unit strides. The host checks these conditions before launch. A transposed or sliced view can retain the expected shape while violating this address formula. Supporting such layouts requires explicit stride arguments or a contiguous copy whose cost is included when relevant. The boundary mask checks column bounds, not layout.
CUDA setup: Running this listing requires a supported NVIDIA GPU and driver, a CUDA-enabled PyTorch build, and a compatible Triton installation. Check torch.cuda.is_available() before allocating the inputs; a false result means this CUDA example cannot run in that environment. Record software and device versions using Appendix A.3, Compatibility checks.
Code example: Triton matrix-vector kernel
import torch
import triton
import triton.language as tl

@triton.jit
def gemv_kernel(A, x, y, M: tl.constexpr, N: tl.constexpr, BLOCK: tl.constexpr):
    row = tl.program_id(0)
    offsets = tl.arange(0, BLOCK)
    acc = tl.full((), 0.0, tl.float32)
    for start in range(0, N, BLOCK):
        cols = start + offsets
        mask = cols < N
        a = tl.load(A + row * N + cols, mask=mask, other=0.0)
        xv = tl.load(x + cols, mask=mask, other=0.0)
        acc += tl.sum(a.to(tl.float32) * xv.to(tl.float32), axis=0)
    tl.store(y + row, acc)

M, N = 4096, 4096
A = torch.randn((M, N), device="cuda", dtype=torch.float16)
x = torch.randn((N,), device="cuda", dtype=torch.float16)
y = torch.empty((M,), device="cuda", dtype=torch.float32)
if A.shape != (M, N) or x.shape != (N,) or y.shape != (M,):
    raise ValueError("Expected A[M,N], x[N], and y[M].")
if A.stride() != (N, 1) or x.stride() != (1,) or y.stride() != (1,):
    raise ValueError("Kernel requires row-major A and unit-stride x/y.")
if not (A.is_cuda and A.device == x.device == y.device):
    raise ValueError("All tensors must share one CUDA device.")
if A.dtype != torch.float16 or x.dtype != torch.float16 or y.dtype != torch.float32:
    raise ValueError("Expected FP16 inputs and FP32 output.")
grid = (M,)
gemv_kernel[grid](A, x, y, M, N, BLOCK=1024)

reference = (A.double() @ x.double()).float()
torch.testing.assert_close(y, reference, rtol=1e-4, atol=1e-3)
The launcher sets a one-dimensional grid with M program instances, one per matrix row. Each instance loads chunks of BLOCK columns, converts the input values to FP32 before multiplication, and reduces the products with tl.sum. With N=4096 and BLOCK=1024, all four chunks are full and the load mask is always true. The mask protects the general case where N is not a multiple of BLOCK. The parameters N and BLOCK specialize the loop and tile size. M is unused inside the kernel and does not need to be tl.constexpr. The final tl.store writes one scalar to global memory, potentially through a cache rather than directly to HBM.
The correctness check uses a wider FP64 PyTorch calculation and converts its result to the output’s FP32 dtype. It runs outside any timing interval. The example tolerances allow finite-precision reduction differences for this input scale. Investigate mismatches rather than widening tolerances merely to pass. Once correctness is established, a tile-size comparison must use the same inputs and completed-work timing boundary taught in the measurement chapter. Since GEMV has low arithmetic intensity, useful changes usually concern coalescing, tile size, register pressure, and parallel work rather than adding arithmetic.
5.6 Attention computation in four tokens
This small attention trace connects the mathematical operation to the tensor shapes that a GPU kernel must load, multiply, normalize, and reduce. The trace uses the query at position four. Its causal mask permits the three earlier keys and the current key, so all four keys in this example remain valid and the mask does not change the scores shown below.
The query represents the current position’s comparison vector. Each key supplies the vector it is compared with, and the dot product gives that key’s score. The corresponding value is the content vector to be mixed into the output. A high score therefore gives that value more weight. Here the key and value rows happen to contain the same numbers, but they have different roles and need not be equal in a model.
Softmax turns a row of scores into positive weights by exponentiating each score and dividing by the sum of those exponentials. For score s_j, its weight is exp(s_j) / sum_i exp(s_i), where i ranges over permitted keys3. This is not division by the sum of the original scores. The attention rule forms query-key scores, scales them by the square root of the head dimension, applies softmax, and mixes the value vectors with those weights.
\[ \text{Attention} = \text{softmax}\left(\frac{Q K^T}{\sqrt{d_{\text{head}}}}\right) V \tag{5.1}\]
Example: Four-token attention
The symbols below fix the dimensions and values for one query position. Keeping the shapes explicit makes each row of the subsequent calculation traceable to a load, matrix operation, reduction, or weighted accumulation. This is a forward attention calculation with fixed inputs, no dropout, and no parameter update.
- Q: One query row with dimensions 1 by 2: [1, 0].
- K: Four key rows with dimensions 4 by 2: [1, 0], [0, 1], [1, 1], and [0, 0].
- V: Four value rows with dimensions 4 by 2: [1, 0], [0, 1], [1, 1], and [0, 0].
- Head dimension: The head dimension is 2, so the scaling factor is the square root of 2.
With those inputs fixed, the table follows the computation in execution order and records both the intermediate value and the tensor dimensions at each step.
| Step | Dimensions | Value | What the kernel is doing |
|---|---|---|---|
| Query-key scores | (1 by 2)(2 by 4) -> 1 by 4 | [1, 0, 1, 0] | Loads one query row and four key rows, then performs dot products. |
| Scale | 1 by 4 | [0.707, 0.000, 0.707, 0.000] | Divides by the square root of 2 before exponentiation to control softmax concentration. |
| Exponentiate | 1 by 4 | [2.028, 1, 2.028, 1] approximately | Applies exp to each scaled score. |
| Sum | Scalar | 6.056 approximately | Adds the four exponentials to form the shared denominator. |
| Normalize | 1 by 4 | [0.335, 0.165, 0.335, 0.165] | Divides each exponential by 6.056 to obtain weights that sum to one. |
| Weighted values | (1 by 4)(4 by 2) -> 1 by 2 | [0.670, 0.500] | Reads value rows and accumulates the weighted output vector. |
For the first score, the query [1, 0] dotted with the first key [1, 0] gives 1*1 + 0*0 = 1. The second key gives 1*0 + 0*1 = 0; the third gives 1*1 + 0*1 = 1; the zero key gives 0. Thus the one-row query multiplied by the transposed four-row key matrix yields [1, 0, 1, 0]. Dividing each score by sqrt(2) produces approximately [0.707, 0, 0.707, 0] before softmax.
\[ Q K^T = [1, 0, 1, 0] \tag{5.2}\]
\[ \text{scaled scores} \approx [0.707, 0.000, 0.707, 0.000] \tag{5.3}\]
\[ \text{attention weights} \approx [0.335, 0.165, 0.335, 0.165] \tag{5.4}\]
\[ \text{attention output} \approx [0.670, 0.500] \tag{5.5}\]
For the scaled scores, exponentiation gives approximately [2.028, 1, 2.028, 1], whose sum is 6.056. Division gives [2.028/6.056, 1/6.056, 2.028/6.056, 1/6.056], or approximately [0.335, 0.165, 0.335, 0.165]. Using the displayed rounded weights, the first output coordinate is 0.335*1 + 0.165*0 + 0.335*1 + 0.165*0 = 0.670. The second is 0.335*0 + 0.165*1 + 0.335*1 + 0.165*0 = 0.500. The output is a weighted mixture of the value rows, not a selected key or a probability vector over features.
The computation exposes the performance distinction used later in the guide. The score matrix has one row in this trace, but for a prompt with T query positions it grows toward T x T. A tiled attention kernel keeps score tiles and softmax state on chip instead of writing the complete score matrix to HBM. The mathematical result stays the same. The memory path changes.
This small attention calculation establishes the mathematical result that an optimized kernel must preserve. The next section shows how FlashAttention changes the movement and storage of intermediate values without changing the attention operation itself.
5.7 FlashAttention and attention-kernel libraries
The same locality ideas used in custom kernels appear in production attention kernels. FlashAttention is an IO-aware attention algorithm and kernel family. It evaluates the standard attention formula without materializing the full N-by-N attention matrix in HBM, streams query, key, and value tiles through on-chip resources, and maintains online softmax statistics. The result is mathematically equivalent to standard attention, while finite-precision evaluation order can change rounding. This IO-aware tiling claim follows FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness4.
The bottleneck it solves is memory traffic. In standard attention, calculating softmax over query-key scores can write and reread an O(N²) matrix. FlashAttention reduces those HBM round trips by fusing the attention computation into tiled kernels. Later versions improve scheduling, parallelism, and hardware utilization rather than changing the definition of attention.
Online softmax evaluates the normalization across successive key blocks while retaining a running maximum and sum. Stable full-row softmax first subtracts the largest score m: p_j = exp(s_j - m) / sum_i exp(s_i - m). Multiplying numerator and denominator by the same exp(-m) leaves the ratio unchanged, while shifted scores are nonpositive and their exponentials cannot overflow.
For one query row, let s_j be a scaled score and v_j its value vector. This explanation uses an unnormalized numerator o = sum_j exp(s_j - m) * v_j and denominator l = sum_j exp(s_j - m) over processed keys. The attention output is o / l only after the final block. This convention follows by multiplying the normalized output in FlashAttention Algorithm 1 by its running denominator5.
The state starts at m = -infinity, l = 0, and a zero vector o with one entry per value feature. For each nonempty block of finite, permitted scores, the update is:
m_new = max(m, max(scores_in_block))andalpha = exp(m - m_new). On the first blockalpha = 0.- For each key in the block,
w_j = exp(s_j - m_new). l_new = alpha * l + sum_j w_jando_new = alpha * o + sum_j w_j * v_j, with these sums restricted to the new block.- Replace
m, l, otogether withm_new, l_new, o_new.
Rescaling works because exp(s_j - m_new) = exp(m - m_new) * exp(s_j - m) for every earlier key. Thus both stored sums remain expressed relative to the new maximum. Masked keys contribute nothing. An all-masked block is skipped, and a row with no permitted keys needs an explicit caller policy because o / l would divide by zero. The example below uses finite scores, at least one permitted key, and no dropout.
Example: Online softmax across two blocks
Inputs: Keep the four value rows from the attention computation trace, but use illustrative scaled scores [0, 0, ln(2), ln(2)], where ln(2) is approximately 0.693. Blocks contain keys 1-2 and 3-4. These scores are chosen to make the second block raise the maximum.
First block: Starting from zero sums, m_new = 0, alpha = 0, and the two exponential weights are [1, 1]. Therefore l = 2 and o = 1*[1,0] + 1*[0,1] = [1,1]. This o is still a numerator.
Second block: The maximum rises from 0 to ln(2), so alpha = exp(-ln(2)) = 0.5. The old state becomes alpha*l = 1 and alpha*o = [0.5,0.5]. The new weights are [1,1]. They add 2 to the denominator and 1*[1,1] + 1*[0,0] = [1,1] to the numerator. The new state is m = ln(2), l = 3, o = [1.5,1.5].
Final normalization and comparison: o/l = [0.5,0.5]. Full-row exponentials without shifting are [1,1,2,2], sum to 6, and give weights [1/6,1/6,1/3,1/3]. Their weighted value sum is also [1/2,1/2]. Rescaling the old numerator and denominator preserved the earlier keys’ contributions despite the higher second maximum. A GPU implementation can therefore discard each score tile after updating this state. Floating-point evaluation can still introduce rounding differences.
Eligibility and speed still depend on dtype, mask, head dimension, sequence shape, and the selected kernel.
- FlashAttention-1: Uses tiled online softmax to evaluate the standard attention result up to floating-point rounding without materializing full score and probability matrices in HBM. Its additional activation storage is linear rather than quadratic in sequence length. IO saving depends on tile shape and available on-chip resources.
- FlashAttention-2: Improves work partitioning across thread blocks and warps, reduces non-matrix-multiplication work, and reduces shared-memory communication. Better sequence-length parallelism can raise occupancy and substantially improve speed over FlashAttention-1 for compatible shapes. These changes follow FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning6.
- FlashAttention-3: Uses Hopper features to overlap movement and computation. Tensor Memory Accelerator (TMA) moves tensors asynchronously between global and shared memory. Warp specialization assigns different warps to data movement and computation. Interleaving matrix multiplication with softmax work adds another source of overlap. Its FP8 path is hardware-dependent and kernel-dependent rather than a generic property of every attention implementation. These Hopper techniques and the FP8 scope follow FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-Precision7.
- xFormers attention kernels: An implementation family of optimized and memory-efficient attention paths. Eligibility and benefit depend on dtype, mask, head dimension, sequence dimensions, and the selected backend. The xFormers project documents memory-efficient exact attention through
xformers.ops.memory_efficient_attentionin xFormers8.
FlashAttention shows how a kernel can reduce HBM traffic without changing the mathematical attention result beyond floating-point ordering and rounding. The next question is whether that traffic reduction, arithmetic throughput, or launch behavior actually limits the measured workload. The performance models supply the bounds, and the measurement chapter supplies the profiler evidence needed to answer it.
References
Tillet, P., Kung, H. T., & Cox, D. (2019). Triton: An Intermediate Language and Compiler for Tiled Neural Network Computations. In Proceedings of MAPL 2019 (pp. 10-19). Triton paper (DOI) (published 2019-06-22). Support: tile-centered language, LLVM-based IR, and tile-level optimization passes for GPU code. Limit: the guide’s modern Triton Python API differs from the 2019 C-based description; mapping and tuning choices still require validation on the intended workload.↩︎
Triton project.
triton.Config, Python API reference for the Triton main branch.triton.ConfigAPI reference. Support:num_warpsis the number of warps used for the kernel, so thatnum_warps=8parallelizes each kernel instance across 8 x 32 = 256 threads, andnum_stagesis the number of stages the compiler uses when software-pipelining loops, described as mostly useful for matrix multiplication on SM80 and later GPUs. Limit: the useful values depend on the kernel, the shapes, and the GPU, so they are found by autotuning rather than read from the documentation.↩︎Dao, T., Fu, D. Y., Ermon, S., Rudra, A., & Re, C. (2022). FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness. FlashAttention paper (v1 2022-05-27; v2 2022-06-23). Support: tiling reduces HBM reads and writes, avoids materializing the full attention matrix, and keeps exact attention up to rounding. Limit: reported speedups are workload specific and IO saving depends on tile shape and on-chip resources.↩︎
Dao, T., Fu, D. Y., Ermon, S., Rudra, A., & Re, C. (2022). FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness. FlashAttention paper (v1 2022-05-27; v2 2022-06-23). Support: tiling reduces HBM reads and writes, avoids materializing the full attention matrix, and keeps exact attention up to rounding. Limit: reported speedups are workload specific and IO saving depends on tile shape and on-chip resources.↩︎
Dao, T., Fu, D. Y., Ermon, S., Rudra, A., & Re, C. (2022). FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness. FlashAttention paper (v1 2022-05-27; v2 2022-06-23). Support: tiling reduces HBM reads and writes, avoids materializing the full attention matrix, and keeps exact attention up to rounding. Limit: reported speedups are workload specific and IO saving depends on tile shape and on-chip resources.↩︎
Dao, T. (2023). FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. FlashAttention-2 paper (v1 2023-07-17). Support: reduced non-matmul work, parallelization across thread blocks, and warp-level work distribution that reduces shared-memory communication. Limit: speed and occupancy gains apply to compatible shapes and hardware, not every attention workload.↩︎
Shah, J., Bikshandi, G., Zhang, Y., Thakkar, V., Ramani, P., & Dao, T. (2024). FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-Precision. FlashAttention-3 paper (v1 2024-07-11; v2 2024-07-12). Support: Hopper TMA asynchrony, warp specialization, matmul-softmax interleaving, and hardware-dependent FP8 path. Limit: FP8 accuracy and speed claims are H100 and kernel specific, not generic attention properties.↩︎
Lefaudeux, B., Massa, F., et al. (2022). xFormers: A modular and hackable Transformer modelling library. xFormers project. Support: README documents memory-efficient exact attention through
xformers.ops.memory_efficient_attentionand states the library dispatches to other libraries and its own CUDA kernels where relevant; the ops documentation lists available memory-efficient attention implementations. Limit: supported dtype, mask, head dimension, and backend combinations change by version and build, so confirm with the installed build usingpython -m xformers.info.↩︎